CDC used to take Kafka, Debezium and a week. Now it's 1 click.
Today we're launching Bruin Cloud Streams: log-based change data capture in Bruin Cloud. Pick a database, start the stream, and every insert, update and delete keeps flowing into your warehouse. One continuous stream, not scheduled batches, and no Kafka cluster to run.
In short
- 1 click, after a one-time database setting. Turn on your database's change log once, then start the stream in Bruin Cloud.
- Seven databases. PostgreSQL, MySQL, MariaDB, SQL Server, MongoDB, Vitess and PlanetScale, each read from its own log.
- Normal tables in your warehouse. Your columns, plus
_cdc_deleted,_cdc_lsnand_cdc_synced_at. - The same engine as ingestr. Cloud Streams runs on ingestr, so you can run the same stream on your own servers too.
Why CDC used to take a week
Reading changes from a database log isn't the hard part. Everything around it is. The usual do-it-yourself setup looks like this:
- Debezium reads the database log and turns each change into an event.
- Kafka stores the events, usually with Kafka Connect and a schema registry next to it.
- A sink connector reads the topics and writes them into the warehouse.
- Everything else: a
docker-compose.ymlthat keeps growing, a dead-letter queue, a backfill script for when a table needs reloading, and alerts for when a connector fails at 3 a.m.
Every box is a service to deploy, upgrade and watch. That stack earns its keep when many systems need the same events, like microservices, search indexes or caches. When the goal is "keep these tables fresh in the warehouse", most of it is overhead. We wrote more about that trade-off in What is CDC streaming?
Managed tools like Fivetran and Airbyte take the servers away, but they copy changes in scheduled syncs. Fivetran's 1-minute syncs need its Enterprise plan.
How Cloud Streams works
Once: turn on the change log. Logical replication and a replication user on Postgres, a row-based binlog on MySQL and MariaDB, CDC or Change Tracking on SQL Server, a replica set or Atlas cluster on MongoDB. On managed databases like AWS RDS this is a parameter change that can need a restart, so plan it with whoever owns the database. For Postgres, our guide to enabling logical replication has the exact setting for RDS, Aurora, Cloud SQL, Azure, Supabase and Neon.
1 click: start the stream. Bruin copies each table once, notes where in the log that copy ends, and follows the log from there.
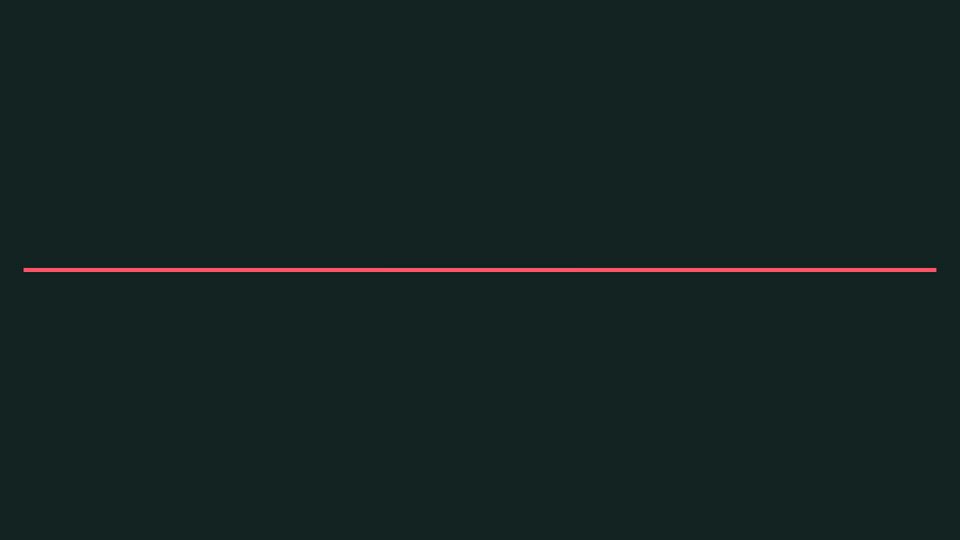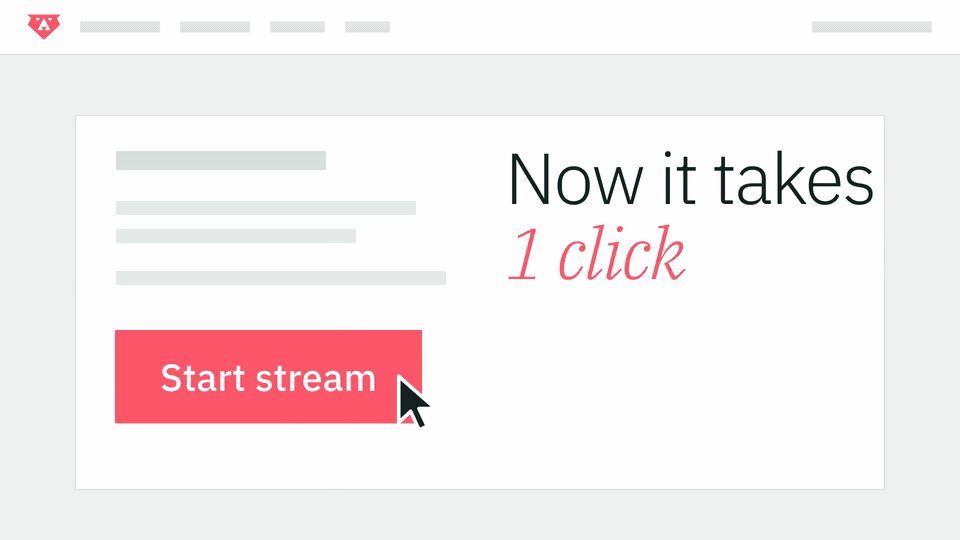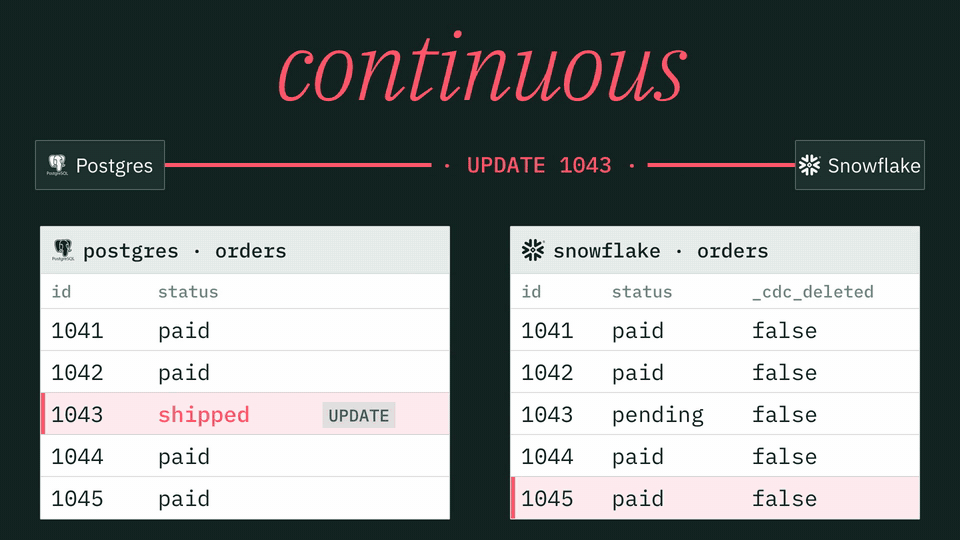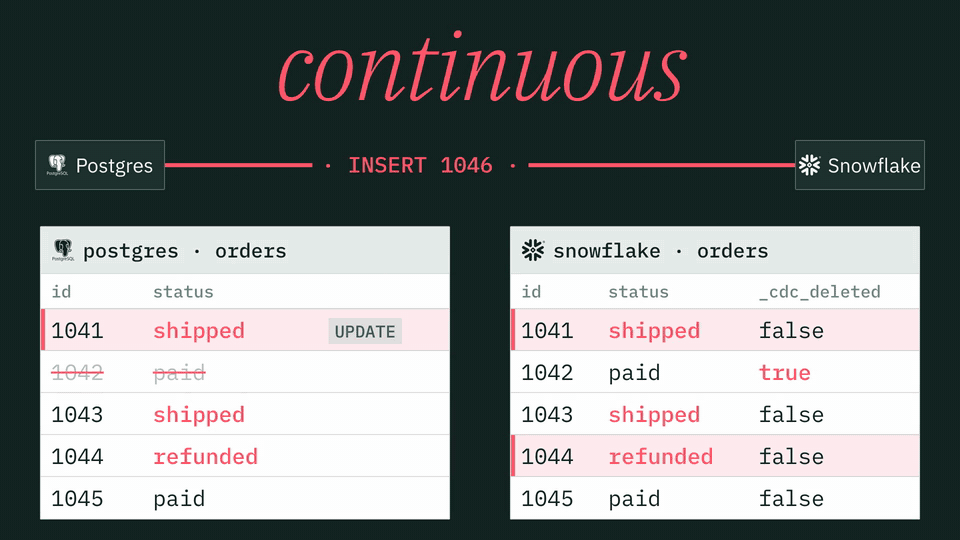
Continuous: changes keep coming. Each insert, update and delete is merged into the warehouse table by primary key. The stream keeps running, so there's no schedule to wait for.
Because the stream reads the log, your production tables are queried once, for the first copy, and not again after that.
What lands in your warehouse
Normal tables. The same columns as the source, plus three that make the CDC state visible:
| Column | What it holds |
|---|---|
_cdc_lsn | The position in the source log for this change |
_cdc_deleted | true when the row was deleted in the source |
_cdc_synced_at | When the change was applied in the warehouse |
Deletes are soft by default: the row stays, flagged, with its last known values, which keeps history easy to debug. To query current rows only:
select *
from analytics.orders
where not _cdc_deleted;
If you'd rather have deleted rows removed, switch to hard deletes.
The parts that usually break
Restarts. If the stream stops, or the warehouse is unreachable for a while, it resumes from the last change it saved, so nothing is skipped. Delivery is at-least-once and every change is merged by primary key, so on tables with a primary key a replay doesn't create duplicate rows.
A log that's gone. If the saved position is no longer in the database log, for example because retention ran out, the stream fails loudly instead of quietly copying half a table. A full refresh rebuilds the table from a fresh copy while the stream keeps running.
Postgres disk. A Postgres replication slot keeps WAL until the stream confirms it, so a stalled stream makes the log grow. Bruin Cloud tracks how far behind each stream is, in WAL bytes for Postgres, and alerts you when it falls behind. More on that in how to stop CDC from filling your Postgres disk with WAL.
New columns. Add a column in Postgres and a running stream picks it up without a restart. Dropped columns stay in the warehouse as empty columns, and a renamed column shows up as a new column next to the old one.
Tables without a primary key. Bruin mirrors tables by primary key. On Postgres, a keyless table with REPLICA IDENTITY FULL is captured as an append-only change log instead. Other databases skip keyless tables with a warning.
Supported databases
| Database | Change log it reads | Turn on once |
|---|---|---|
| PostgreSQL | Logical replication (WAL) | wal_level=logical and a user with REPLICATION |
| MySQL and MariaDB | Binary log (binlog) | binlog_format=ROW and binlog_row_image=FULL |
| SQL Server | CDC or Change Tracking | Enable it for the database and each table |
| MongoDB | Change streams | A replica set or an Atlas cluster |
| Vitess | VStream, across every shard | Access to vtgate's gRPC port |
| PlanetScale | PlanetScale's hosted change API | Database credentials with read access |
Streams write to BigQuery, Snowflake, StarRocks, PostgreSQL, MySQL, SQL Server and DuckDB, among others. One limit to know: MySQL and MariaDB streams need a destination that enforces primary keys, so not BigQuery or Snowflake.
The setup steps for each database are in the ingestr CDC docs.
Cloud Streams, a DIY stack, or Fivetran and Airbyte
| Compared on | Kafka + Debezium, built yourself | Fivetran or Airbyte | Bruin Cloud Streams |
|---|---|---|---|
| What you run | Kafka, Kafka Connect, Debezium and a sink connector | Nothing | Nothing |
| Setup | Days to weeks | A setup wizard per source | 1 click, once the change log is on |
| How changes arrive | A continuous stream | Scheduled batch syncs. Fivetran's 1-minute syncs need its Enterprise plan | One continuous stream |
| Run the engine yourself | Yes | Airbyte: yes. Fivetran: no | Yes, with ingestr |
Run it yourself with ingestr
Cloud Streams runs on ingestr, our ingestion CLI. The same stream runs on your own machine or servers:
ingestr ingest \
  --source-uri 'postgres+cdc://user:pass@host:5432/app?dest_schema=analytics' \
  --dest-uri 'bigquery://my-project?credentials_path=/path/to/sa.json' \
  --stream
ingestr is source-available under the Functional Source License. Bruin Cloud adds everything around the process: it keeps the stream running, tracks lag and alerts you. When we launched ingestr CDC in July, we explained how the engine works under the hood, and named "making CDC streams easier to operate in Bruin Cloud" as what came next. Cloud Streams is that.
Security
Cloud Streams runs in Bruin Cloud, which is ISO/IEC 27001:2022 certified and SOC 2 Type 2 attested. For databases on a private network, VPC peering and private connectivity options are available for enterprise tenants. The details are on our security page.
When you don't need CDC
CDC isn't always the answer. If your tables have a reliable updated_at column, you don't need deletes, and a refresh every hour is fine, then incremental loading is simpler and doesn't touch any database settings.
CDC earns its place when deletes matter, when there's no change column you can trust, or when re-reading big tables costs too much. For a wider look at the options, see our comparison of CDC tools.
FAQ
Do I need Kafka or Debezium to use Bruin Cloud Streams?
No. Bruin reads the database log directly and merges each change into your warehouse, so there is no Kafka cluster or connector to run.
What do I need to set up on my database before streaming with Bruin?
Turn on the change log once: logical replication and a replication user on Postgres, a row-based binlog on MySQL, CDC or Change Tracking on SQL Server, a replica set or Atlas cluster on MongoDB. On managed databases such as AWS RDS this is a parameter change that can need a restart.
Which databases and warehouses does Bruin Cloud Streams support?
It reads PostgreSQL, MySQL, MariaDB, SQL Server, MongoDB, Vitess and PlanetScale from their own change logs, and writes to BigQuery, Snowflake, StarRocks, PostgreSQL, MySQL, SQL Server and DuckDB, among others. MySQL and MariaDB streams need a destination that enforces primary keys, so not BigQuery or Snowflake.
How does Bruin Cloud Streams handle deleted rows?
By default a deleted row stays in the warehouse with _cdc_deleted set to true, so you keep its last values. Switch to hard deletes and the row is removed.
What happens if a Bruin stream stops or the warehouse is down?
The stream resumes from the last change it saved, so nothing is skipped. Delivery is at-least-once and changes are merged by primary key, so on tables with a primary key a replay doesn't create duplicate rows.
How is Bruin Cloud Streams different from Fivetran or Airbyte?
Fivetran and Airbyte copy changes in scheduled batches, and Fivetran's 1-minute syncs need its Enterprise plan. Cloud Streams is one continuous stream, on ingestr, an engine you can also run yourself.
Can I run the same CDC without Bruin Cloud?
Yes. ingestr ingest --stream runs the same stream on your own machine or servers; ingestr is source-available under the Functional Source License. Bruin Cloud keeps it running, tracks lag and alerts you.
Try Cloud Streams
Cloud Streams is live in Bruin Cloud. See how it works or try Bruin for free.