The Bruin Blog
Insights, ideas, and stories from the Bruin team.
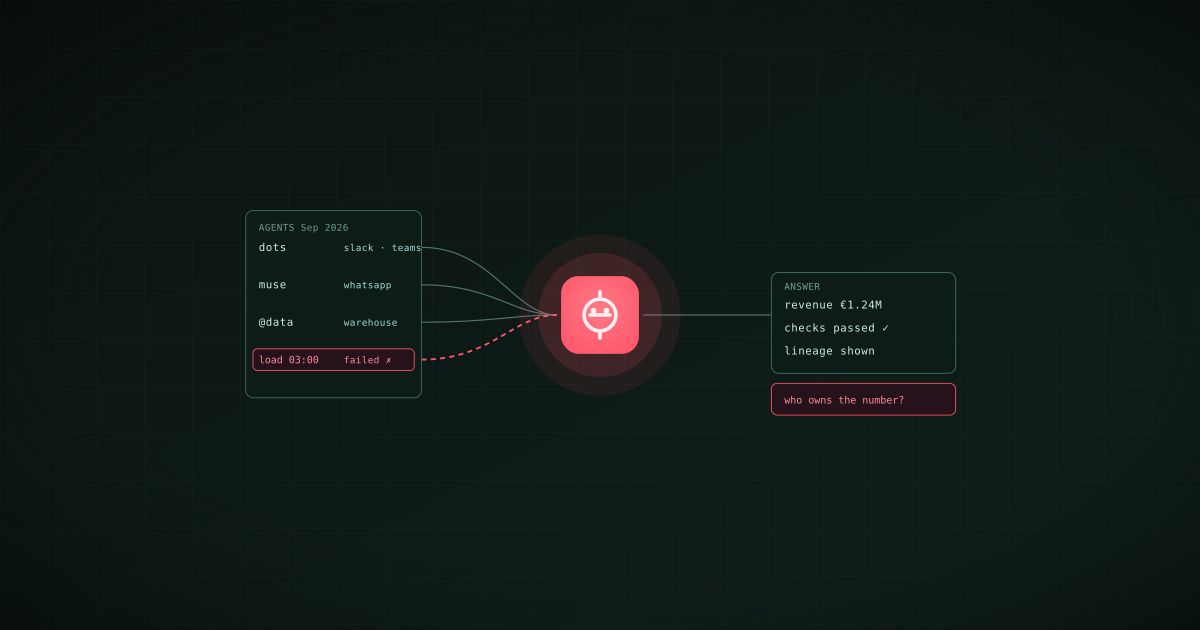
ChatGPT Dots, Meta Muse, and the ChatGPT Data Agent: Can They Answer Questions About Your Company Data?
OpenAI launched Dots, always-on agents in Slack and Teams, three weeks after its Data agent for ChatGPT Work. Meta opened Muse to small businesses on WhatsApp the same day. Here is what each one can and cannot do with company data, compared with an AI data analyst such as Bruin that owns the pipeline underneath the answer.

Kateryna Kozachenko
8 min read
Snowflake ETL Tools: How 52,771 Companies Load Data (2026)
Fivetran leads at 12.7% of 52,771 Snowflake companies, then ADF, Informatica, AWS Glue, Airbyte, and Matillion. How the top Snowflake ETL tools compare.

Arsalan Noorafkan
15 min read
100 Analytics Engineering Questions for 2026, Answered
Short, practical answers to 100 analytics engineering questions for 2026: SQL, data modeling, testing, semantic layers, Git, AI agents, tools, and careers.
Arsalan Noorafkan
28 min read
100 Data Engineering Questions for 2026, Answered
Short, practical answers to 100 data engineering questions for 2026: ingestion, orchestration, lakehouses, data quality, governance, AI agents, and careers.
Arsalan Noorafkan
30 min read
What Is Dashboards as Code? Code-First BI Explained
Dashboards as code means a dashboard is a file in a git repository, a YAML or code definition of its metrics, charts, and filters, that is reviewed in a pull request and deployed on merge, instead of an object clicked together in a BI tool. This explainer covers what the file contains, why teams switch, the AI angle, and how Bruin, Lightdash, Evidence, and Rill implement it.
Kateryna Kozachenko
6 min read
What Is Impact Analysis for a Schema Change? Finding What Breaks Before You Rename a Column
Impact analysis is the step before a schema change where you find every model, check, dashboard, and consumer that depends on the column or table you are about to alter. This explainer covers why it needs column-level lineage rather than table-level, how to run it from the command line with Bruin, and what dbt, Airflow, and catalog tools give you instead.
Kateryna Kozachenko
6 min read
What Is an MCP Server for Data Tools? How AI Agents Query Pipelines and Warehouses
An MCP server is a program that exposes a tool's capabilities, running a query, reading lineage, validating a pipeline, to any AI agent that speaks the Model Context Protocol, so Claude Code, Cursor, or ChatGPT can operate the tool directly. This explainer covers what an MCP server does for data work, what a good one exposes, and how Bruin's compares with the MCP servers from dbt, Snowflake, Databricks, and BigQuery.
Kateryna Kozachenko
6 min read
What Is Data Observability? And How It Differs From Data Testing
Data observability is the practice of monitoring the health of data in production, freshness, volume, schema, distribution, and lineage, so problems are detected without someone writing a check for each one. Data testing asserts what must be true before data ships. This explainer covers the five signals, why both are needed, and how Bruin, Monte Carlo, Elementary, and Great Expectations divide the work.
Kateryna Kozachenko
6 min read
What Is ELT? ELT vs ETL, and Which One Modern Data Pipelines Use
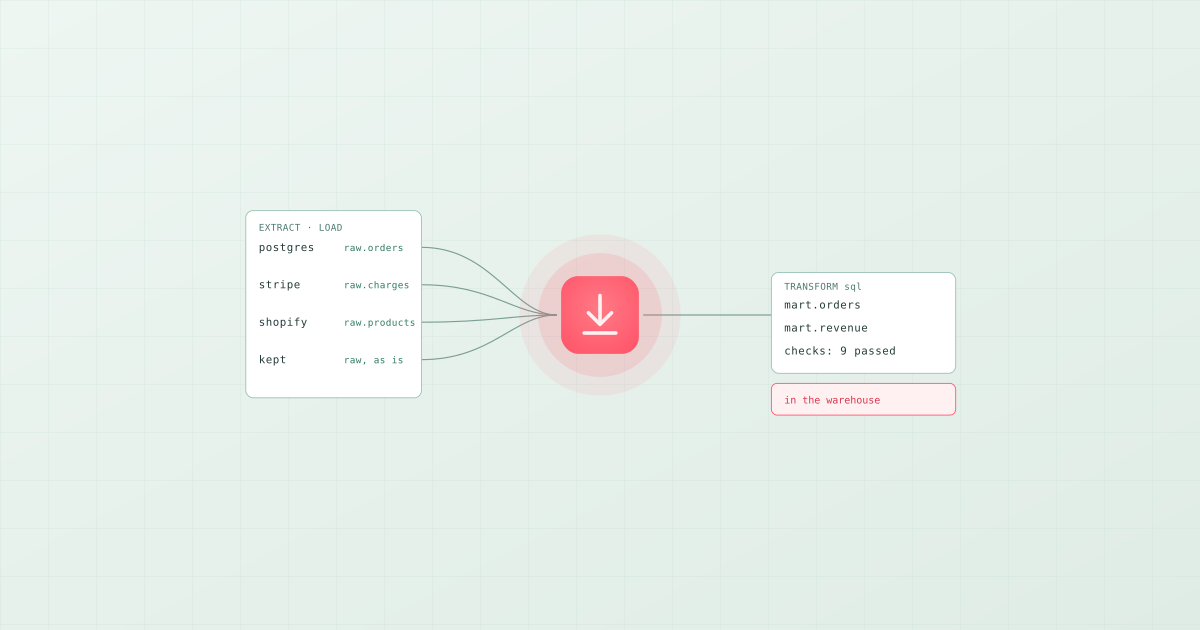
ELT means extract, load, transform: copy raw data into the warehouse first, then transform it there with SQL. ETL transforms before loading. This explainer covers the difference, why warehouses made ELT the default, when ETL still wins, and how Bruin, dbt, Fivetran, and Airbyte fit each pattern.
Kateryna Kozachenko
6 min read
Best data migration tools in 2026: strategies, trade-offs, and a realistic plan
An objective comparison of data migration tools in 2026, including ingestr, Bruin CLI, Airbyte, Fivetran, dlt, Debezium, Estuary Flow, Sling, Meltano, AWS DMS, and Google Datastream.
Arsalan Noorafkan
16 min read
Prepping Your Ecommerce Analytics for BFCM and the Q4 Peak
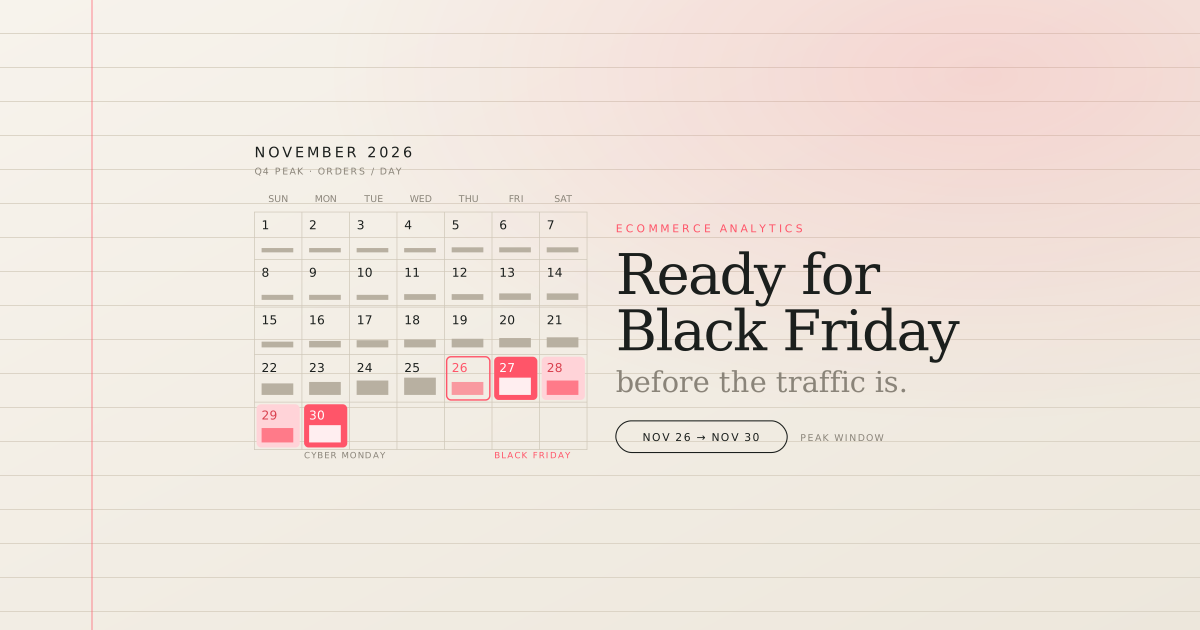
Black Friday 2026 is November 27 and Cyber Monday is November 30. A practical September-to-January plan for getting your ecommerce analytics ready for peak: which numbers to lock down, what breaks under load, a month-by-month checklist, and how an AI data analyst like Bruin keeps the answers trustworthy when volume is 10x.
Kateryna Kozachenko
12 min read
Modern Data Ingestion and Integration Strategies in 2026
A practical guide to evaluating data ingestion in 2026: CDC, connector coverage, schema changes, reliability, cost, open-source deployment, and Snowflake, Databricks, and BigQuery destinations.
Arsalan Noorafkan
15 min read
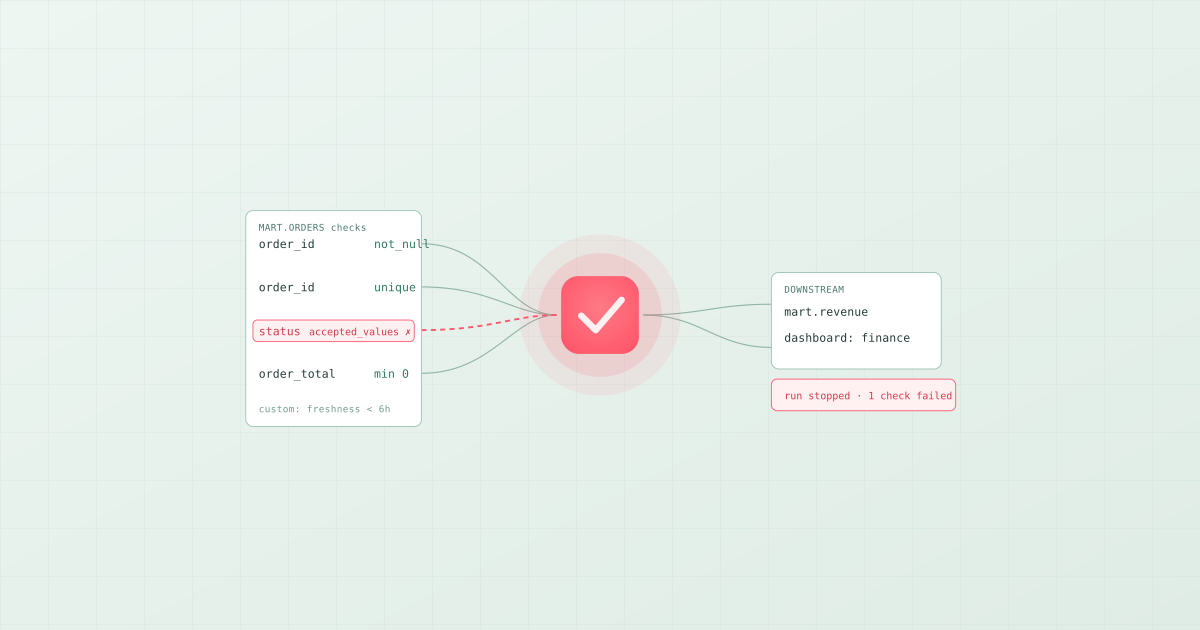
Data Quality and Testing Strategies for Modern Data Pipelines
How to test data as part of a pipeline in 2026: which open-source data quality frameworks to use, how to add checks that block bad data before it lands, how to monitor freshness and completeness, and how to enforce data contracts between producers and consumers. Bruin, Great Expectations, Soda, dbt tests, Elementary, and Monte Carlo compared by where they run.
Kateryna Kozachenko
12 min read
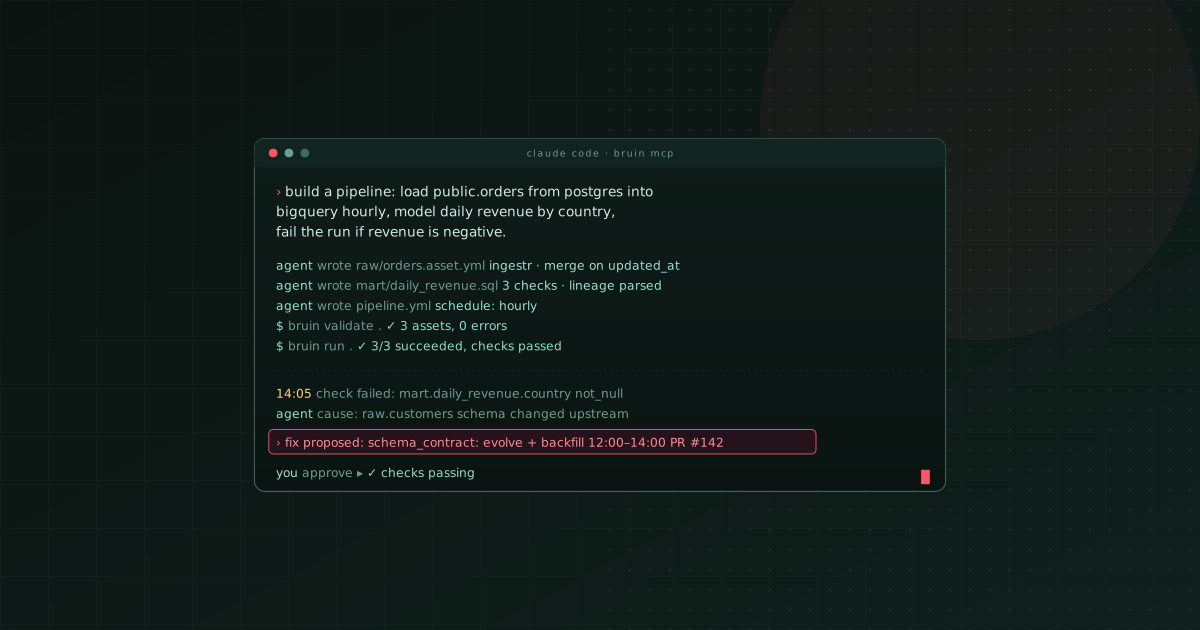
How to Build and Maintain Data Pipelines with AI Agents
A step-by-step 2026 guide to using AI agents for data engineering: define a pipeline in natural language, let the agent build ingestion, SQL and Python assets, add quality checks it can read, and run a detect, diagnose, fix, verify loop for self-healing. Covers Bruin MCP with Claude Code, Cursor and Codex, plus dbt, Databricks and Dagster options.
Kateryna Kozachenko
12 min read
How to Learn SQL in the Age of AI: Review the Query, Not Just the Syntax
Learning SQL in the age of AI means more than memorising syntax. Learn how to review, question, and verify the SQL an agent writes with Bruin Academy's interactive course.
Arsalan Noorafkan
9 min read
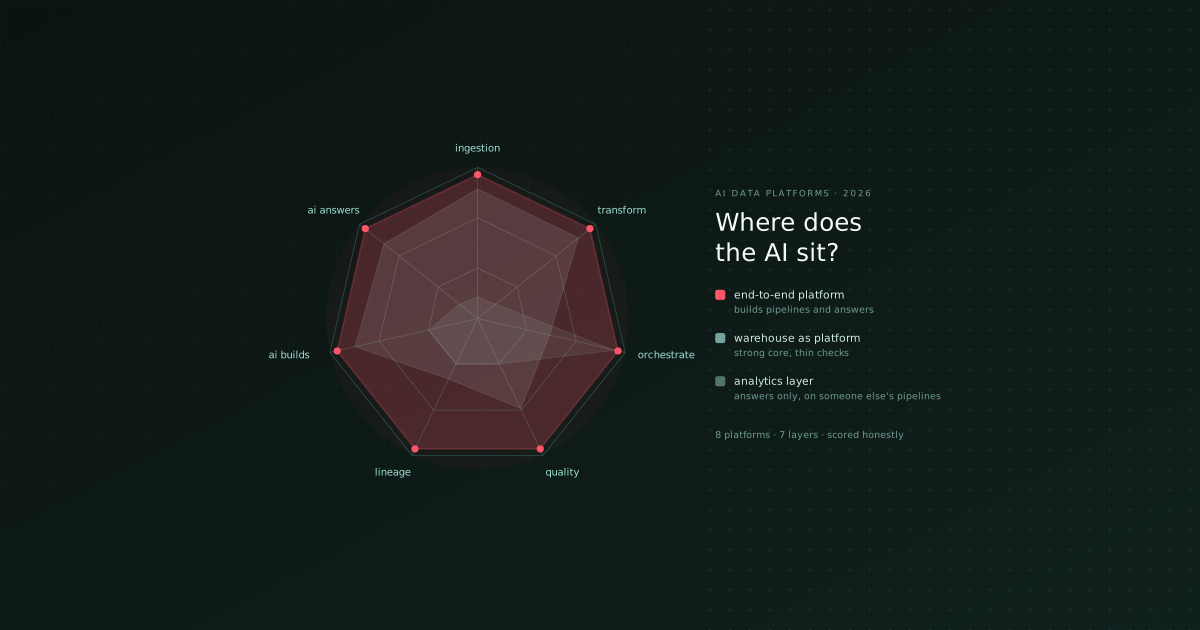
The Best AI Data Platforms in 2026
An honest 2026 comparison of AI data platforms: Bruin, Databricks, Snowflake Cortex, Microsoft Fabric, BigQuery with Gemini, Dagster Compass, ThoughtSpot and Hex. Which ones handle ingestion, pipelines and analytics in one tool, which have built-in quality checks, lineage and a catalog, which work in Slack, Teams and Discord, and which is the cheapest way to replace several tools.
Kateryna Kozachenko
12 min read
Chargebee Analytics in BigQuery: MRR, Retention, and Dunning Without a Reporting Silo
Build a Chargebee to BigQuery pipeline with open-source Bruin and ingestr. Model MRR, retention, plan mix, revenue concentration, and failed-payment risk in SQL your team can review.
Arsalan Noorafkan
12 min read
The Best End-to-End Data Platforms in 2026
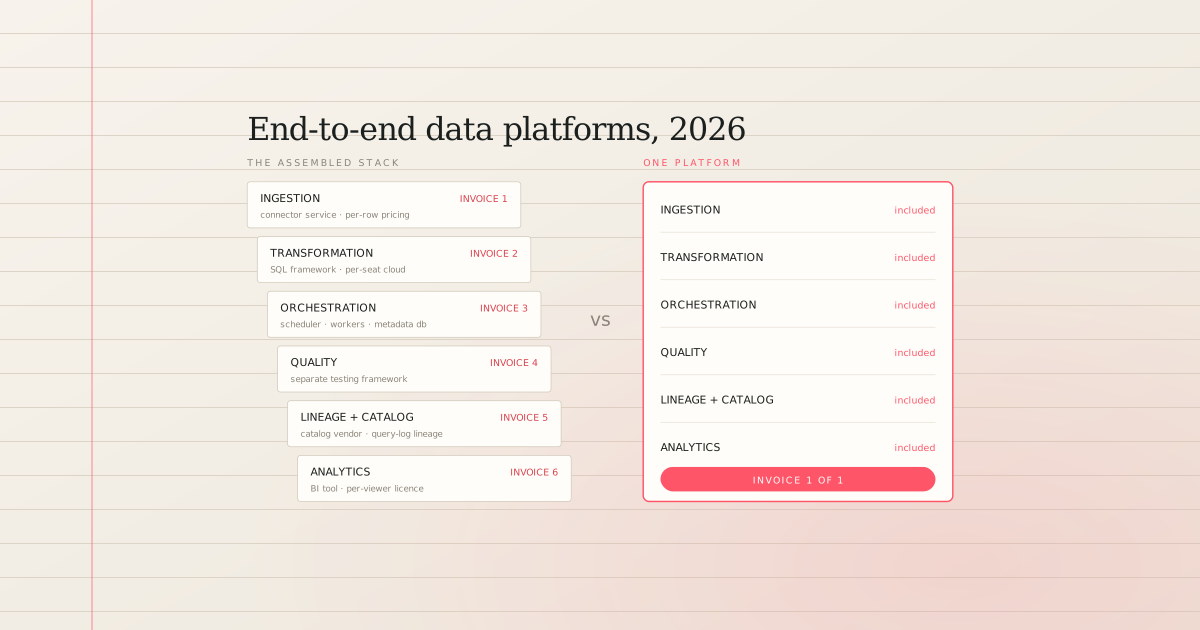
An honest 2026 guide to end-to-end and all-in-one data platforms: Bruin, Databricks, Microsoft Fabric, Snowflake, Keboola, Y42, Rivery, Mage, and the assembled Fivetran, dbt, and Airflow stack. Which one replaces the most tools, which is open source, which fits a small team, and what a unified data stack should actually include.
Kateryna Kozachenko
13 min read
Near-real-time payments & fraud monitoring on ClickHouse
A walkthrough of Bruin's payments and fraud monitoring demo: PostgreSQL change capture, one-minute ClickHouse rollups, late-arriving restatements, sealed daily KPIs, and a dashboard you can run locally.
Arsalan Noorafkan
12 min read
Which Data Tools Have a Built-in MCP Server in 2026
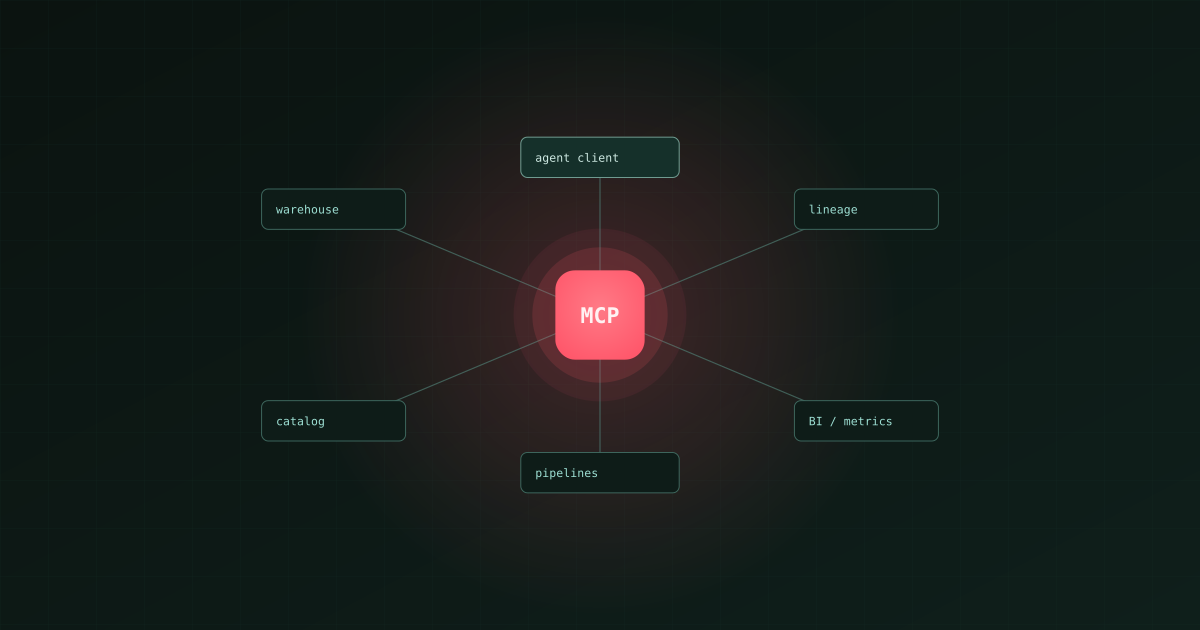
A 2026 guide to MCP servers in the data stack. Which data tools ship one (Bruin, dbt, Snowflake, Databricks, Atlan and more), what an agent can actually do through each, how to connect an LLM agent to your pipelines, and why lineage and metric definitions decide whether the answers are right.
Kateryna Kozachenko
11 min read
PostHog Product Analytics Pipeline: Why Group Analytics Runs Out and How to Build Your Own
PostHog is excellent at what it does and silent outside its own boundary: no retroactive account rollup, no join to billing or CRM, and an events API with a backfill trap most teams find the hard way. Here is where PostHog's own reporting stops, how a three-layer pipeline fixes it, and why starting from a free local template beats assembling a stack.
Arsalan Noorafkan
13 min read
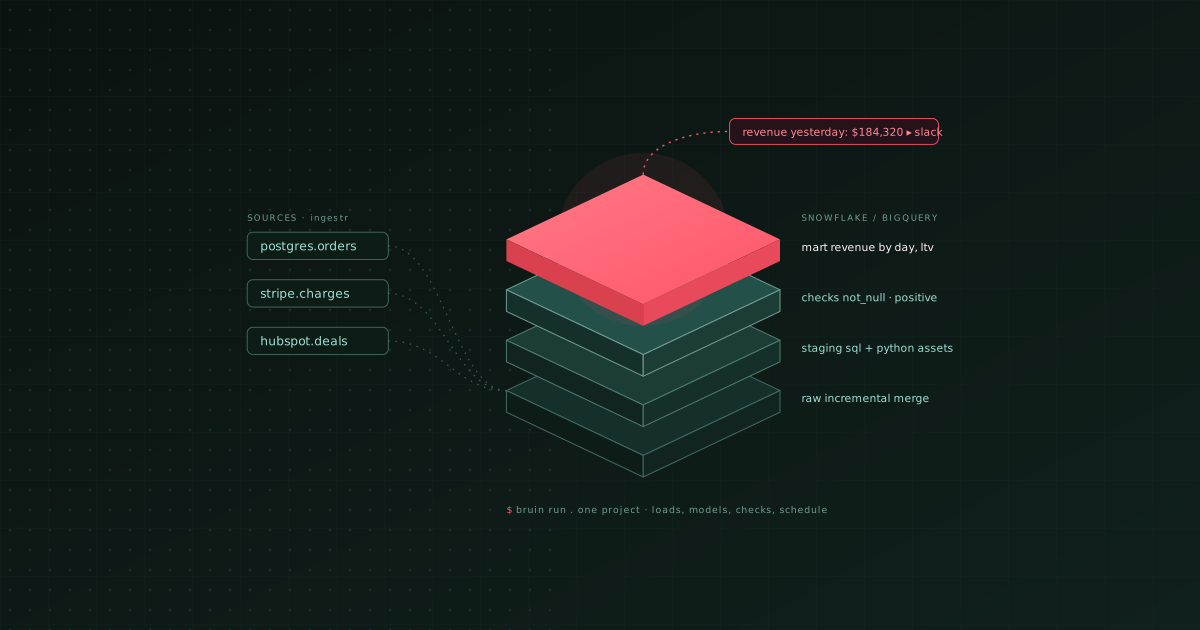
How to Build an End-to-End Data Pipeline on Snowflake or BigQuery
A step-by-step 2026 guide to building a complete data pipeline on Snowflake or BigQuery: set up the warehouse, move data from Postgres and APIs with incremental loads, model it with SQL and Python, add quality checks, schedule it, and keep compute costs down. One Bruin project instead of a loader, a transformation framework and an orchestrator.
Kateryna Kozachenko
13 min read
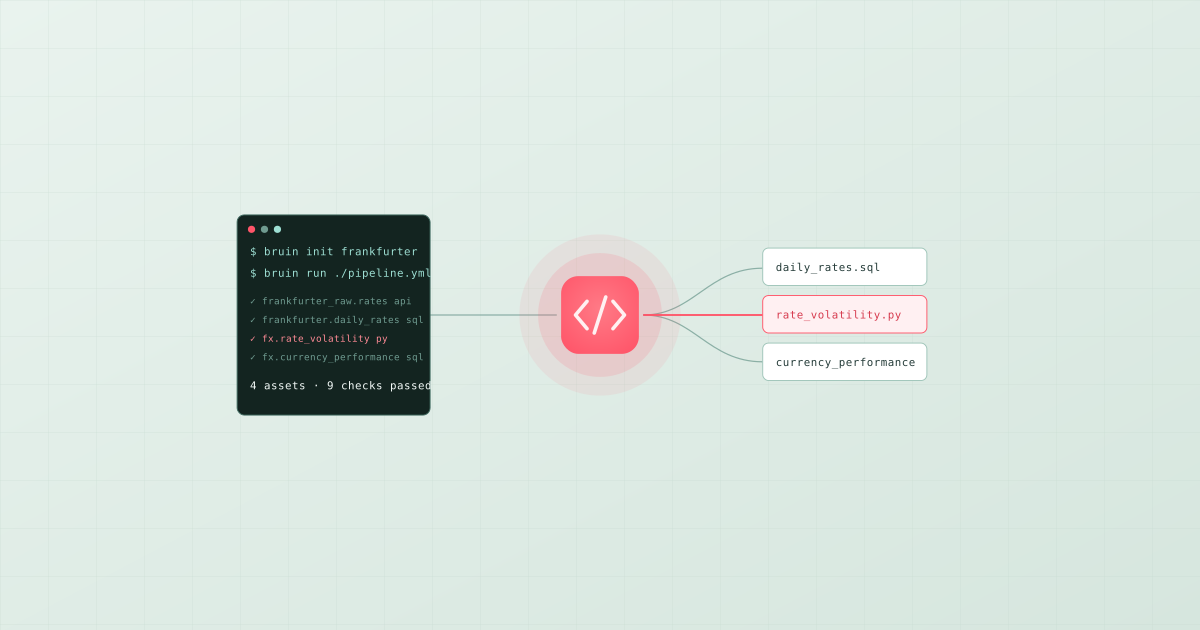
How to Build Your First ELT Pipeline with SQL and Python
A step-by-step 2026 guide to building a first data pipeline: pull data from a public API, land it in a warehouse, transform it with SQL and Python in one project, add quality checks, and schedule it. Runs locally on DuckDB in ten minutes, then points at Snowflake, BigQuery, or Databricks by changing one connection. Built with Bruin's open-source CLI.
Kateryna Kozachenko
11 min read
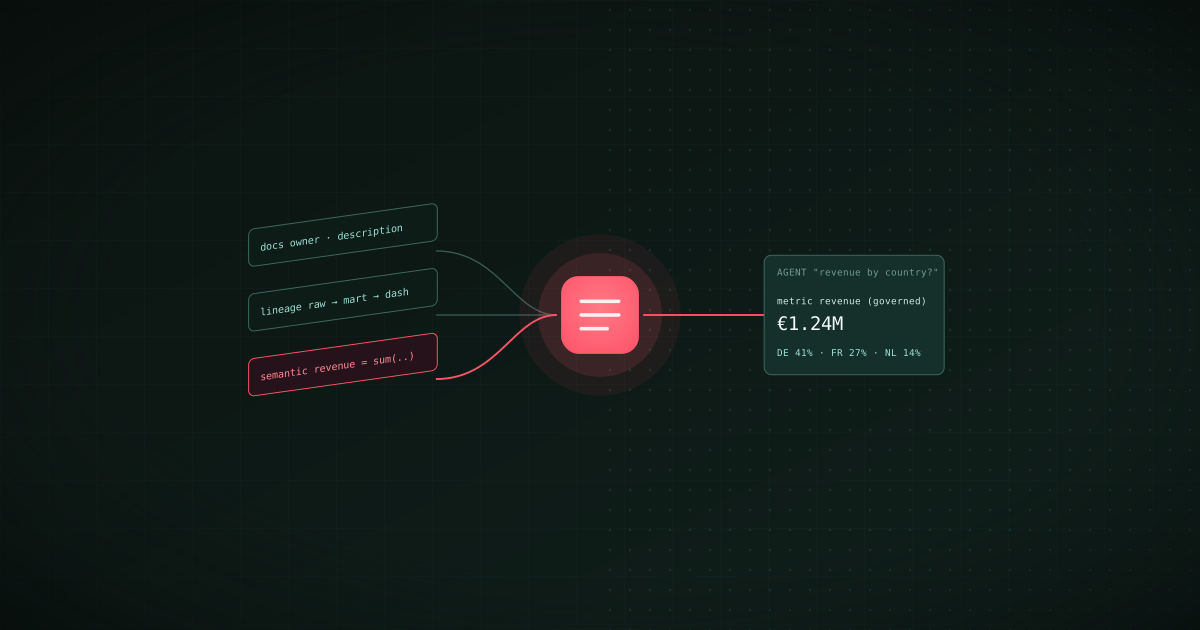
How to Build a Context Layer for AI-Ready Data Pipelines
A step-by-step guide to giving AI agents the context they need to query company data correctly: automate pipeline documentation, establish column-level lineage so schema changes show their downstream impact, and publish a semantic layer of governed metrics that an AI data analyst or a coding agent reads through MCP. Built with Bruin's open-source CLI.
Kateryna Kozachenko
12 min read
What Is a Data Quality Check? Types, Where to Run Them, and Examples
A data quality check is a rule that runs against a table and fails when the data breaks it: not null, unique, accepted values, ranges, referential integrity, freshness. This explainer covers the check types, why the check should live in the pipeline that produces the table, and how to add checks to a pipeline with Bruin, dbt, Great Expectations, or Soda.
Kateryna Kozachenko
6 min read
What Is Data Freshness? How to Measure and Monitor It in a Pipeline
Data freshness is how old the newest row in a table is relative to now, and completeness is whether the expected rows arrived. This explainer covers how to define an SLA for both, how to check them inside the pipeline with a freshness check and a row-count check, and where dbt source freshness, Bruin custom checks, and observability tools fit.
Kateryna Kozachenko
6 min read
What Is a Data Contract? Definition, Example, and How to Enforce One
A data contract is an agreement between the team that produces a table and the teams that consume it: the columns, types, guarantees, and how changes are announced. This explainer shows what a contract contains, why it only works as code, and how to enforce it at build time with policies and at run time with blocking checks, using Bruin, dbt model contracts, and Soda.
Kateryna Kozachenko
6 min read
What Is Column-Level Data Lineage? How It Works and Why It Beats Table-Level
Column-level lineage traces each output column back to the exact source columns and transformations that produced it, rather than stopping at the table. This explainer covers how it is derived (parsing SQL versus reading query logs), what it is for (impact analysis before a schema change, root cause after a break), and the tools that provide it: Bruin, OpenMetadata, DataHub, Atlan, and dbt.
Kateryna Kozachenko
6 min read
What Is Pipelines as Code? Managing Data Pipelines Like Software
Pipelines as code means every part of a data pipeline, the loads, the SQL and Python transformations, the quality checks, the schedule, lives as files in a git repository, is validated on every pull request, and is deployed on merge. This explainer covers what belongs in the repository, the two CI jobs that make it work, and how Bruin, dbt, and Dagster implement it.
Kateryna Kozachenko
6 min read
What Is an AI Data Analyst? How It Differs From BI Tools and Chatbots
An AI data analyst is a system that answers business questions from live, governed company data in plain English, inside the tools a team already uses, and can build dashboards and act on the answer. This explainer covers what it is, how it differs from a BI tool and from ChatGPT on a spreadsheet, what makes its answers accurate, and how to evaluate one.
Kateryna Kozachenko
6 min read
What Is Agentic Data Engineering? AI Agents That Build and Repair Pipelines
Agentic data engineering is the practice of letting an AI coding agent build, run, test, and repair data pipelines, with a human reviewing the diff. This explainer covers what an agent can actually do for a pipeline, what the pipeline has to look like for that to be safe, how MCP connects the agent, and where Bruin, dbt's MCP server, Databricks Genie, and Dagster Compass fit.
Kateryna Kozachenko
6 min read
What Is a Data Orchestrator? And When a Small Team Does Not Need One
A data orchestrator schedules pipeline tasks, runs them in dependency order, retries failures, and records what ran. This explainer covers what Airflow, Dagster, and Prefect actually do, what it costs to operate one, and why a pipeline framework that resolves its own dependency graph, such as Bruin, removes the orchestrator for teams whose DAGs are mostly ELT glue.
Kateryna Kozachenko
6 min read
What Does a Modern Data Stack Cost? The Pricing Models, With Vendor Numbers
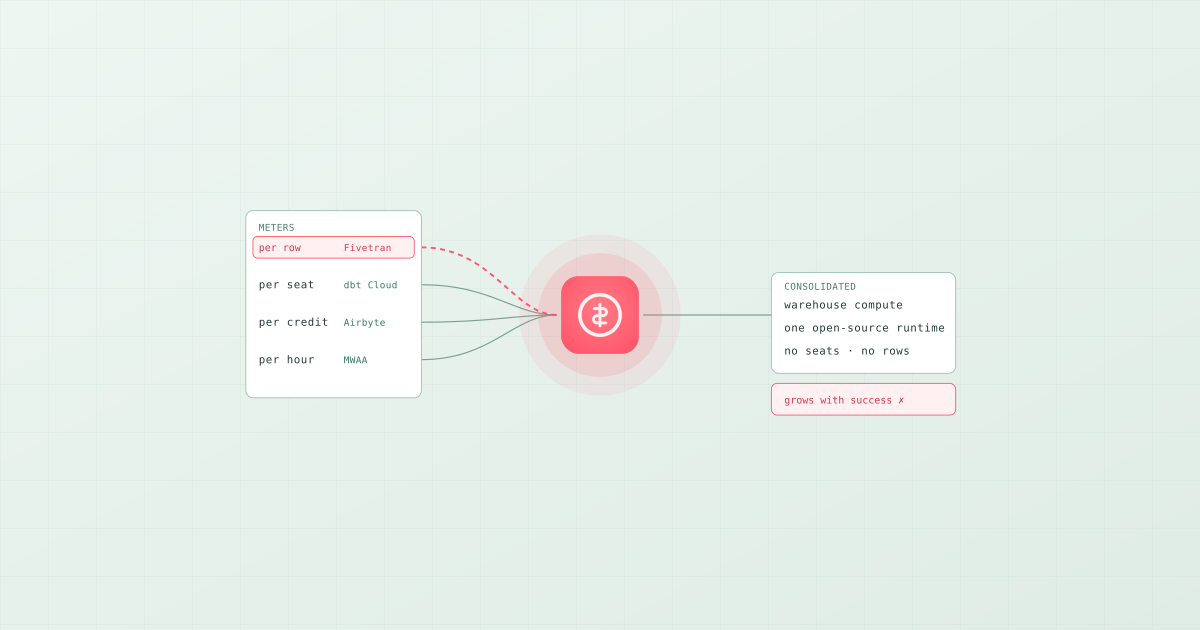
A modern data stack is priced by four different meters: per monthly active row (Fivetran), per developer seat (dbt Cloud), per credit (Airbyte), and per environment-hour (Amazon MWAA), plus warehouse compute. This explainer shows what each meter charges at list price, which ones grow faster than your data, and why consolidating the stack into one open-source runtime is the largest single saving.
Kateryna Kozachenko
7 min read
What Is a Self-Healing Data Pipeline?
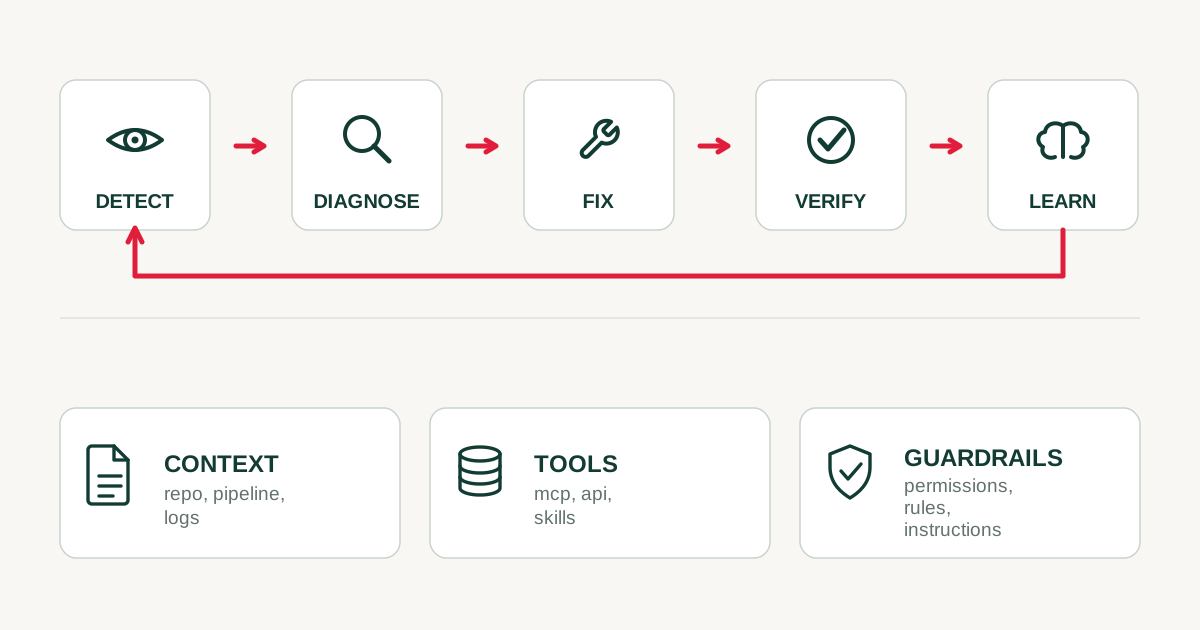
A conceptual guide to self-healing data pipelines: what they are and are not, why incident response is mostly evidence gathering that agents are good at, the detect-diagnose-fix-verify-learn loop, the checks, lineage, and editable definitions that make it possible, and the guardrails that keep it safe.
Arsalan Noorafkan
11 min read
How to Build an AI Context Layer for Your Data Warehouse
A practical guide to mapping your tables and generating a version-controlled AI context layer with two free, open-source commands: bruin import database and bruin ai enhance.
Arsalan Noorafkan
12 min read
The Best Data Lineage and Catalog Tools in 2026
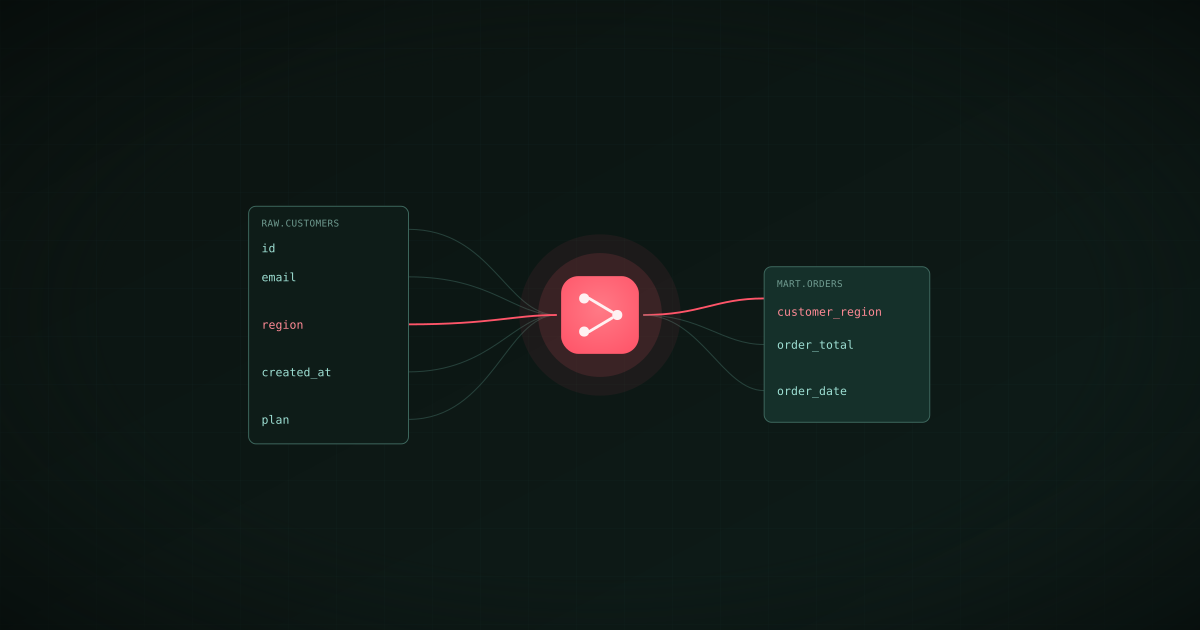
An honest 2026 guide to data lineage and catalog tools, from Atlan and Collibra to OpenMetadata, DataHub, dbt, and Bruin. Which give column-level lineage, which are open source, which show downstream impact before a schema change, and which build the context an AI agent needs.
Kateryna Kozachenko
13 min read
What Is Headless BI? Code-First Analytics for Developers, Explained
Headless BI separates the metric definitions and query engine from any particular dashboard front end, exposing governed metrics through an API that any tool or agent can call. This explainer covers how it differs from traditional and code-first BI, what a headless setup looks like in practice, and the tools: Cube, Bruin, Lightdash, Evidence, and the dbt Semantic Layer.
Kateryna Kozachenko
6 min read
How Hard Is It to Migrate to Bruin? The Honest Answer, Tool by Tool
Migrating to Bruin is incremental, not a rewrite: bruin import database turns existing warehouse tables into assets in one command, dbt models port with their Jinja, the Fivetran migration template maps connectors to ingestr loads with an approval gate, and Bruin runs from an existing Airflow DAG while you move. This guide covers the order to do it in, how long each step takes, and what the CLI-first workflow means for people who do not live in a terminal.
Kateryna Kozachenko
8 min read
Does Bruin Lock You In? What You Own, and How You Would Leave
A plain statement of what a Bruin customer owns: pipelines as SQL, Python, and YAML in your own Git repository, data that never leaves your own warehouse, and an Apache 2.0 CLI that runs anywhere, including inside Airflow. It covers what Bruin Cloud adds, what happens if you stop paying, and the one place a dependency exists. Written to be checked, not believed.
Kateryna Kozachenko
6 min read
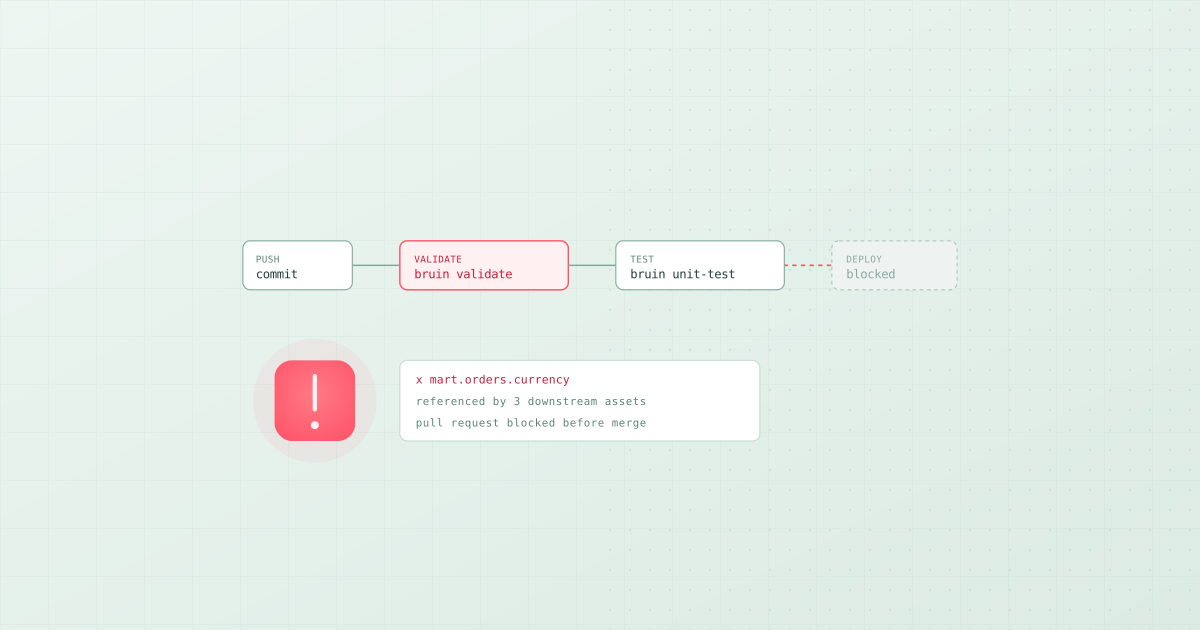
How to Run Data Pipelines in CI/CD
A practical 2026 guide to running data pipelines in CI/CD with Bruin. A working GitHub Actions workflow, the GitLab and Azure equivalents, what to validate on a pull request versus deploy on merge, how to test only changed assets, and how to enforce data contracts before a schema change ships.
Kateryna Kozachenko
12 min read
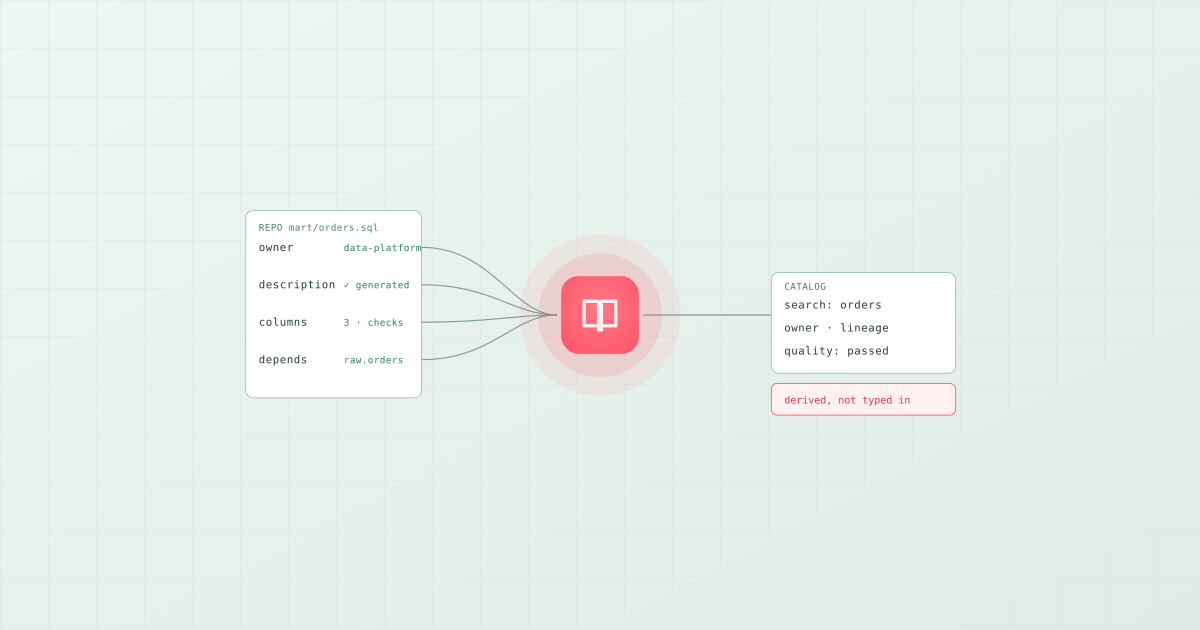
What Is a Data Catalog? And Whether a Small Data Team Needs One
A data catalog is an inventory of an organisation's data assets: tables, columns, owners, descriptions, lineage, and quality status, searchable in one place. This explainer covers what a catalog holds, the two ways one gets populated, and why a small team is better served by a catalog generated from the pipeline than by a standalone product. Tools: Bruin, OpenMetadata, DataHub, Atlan, Collibra.
Kateryna Kozachenko
6 min read
What GA4 and Search Console Will Never Tell You (And How to Get It Anyway)
Search Console stops at the click. GA4 never receives the query. The reports that actually change what you build live in the join between them, and neither product will do that join for you.
Arsalan Noorafkan
11 min read
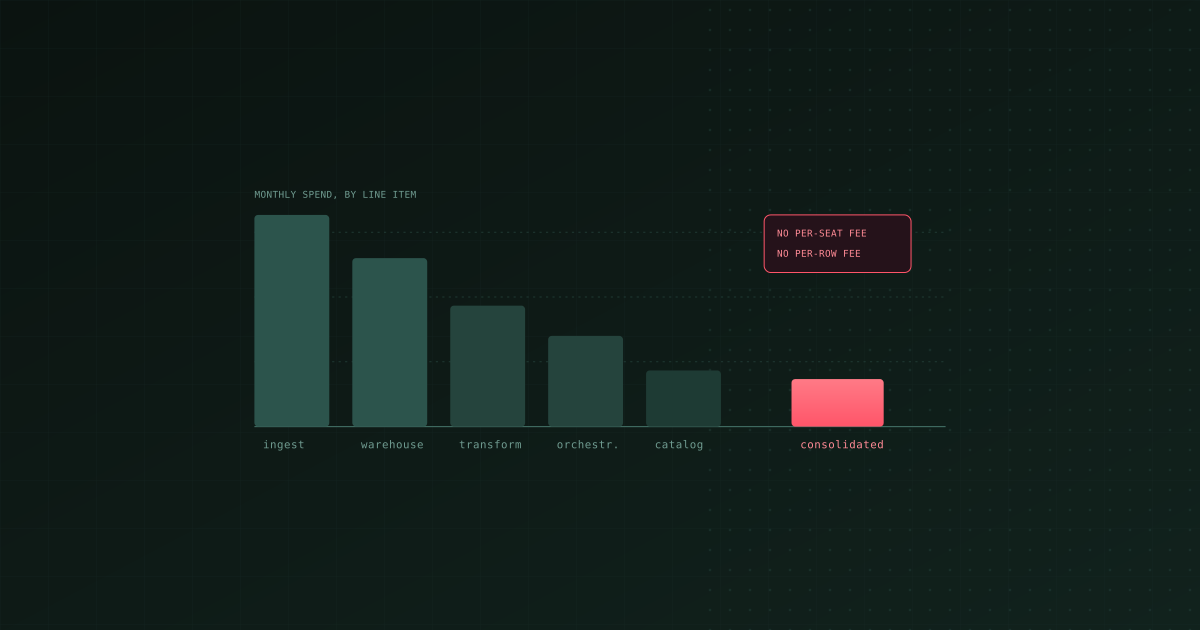
The Cheapest Modern Data Stack in 2026
How to build a data platform on a small budget in 2026. Where the money actually goes, which pricing models bite at scale, the cheapest reference stack for a lean team (Bruin plus a pay-per-query warehouse), and how to cut Snowflake and BigQuery costs without cutting scope.
Kateryna Kozachenko
13 min read
Column Aliases in HAVING: BigQuery vs ClickHouse vs Postgres vs DuckDB
The same HAVING clause runs on Postgres and DuckDB and fails on BigQuery and ClickHouse. A tested four-engine comparison, with a fixture you can run.
Arsalan Noorafkan
12 min read
The Best Data Quality Tools in 2026
An honest 2026 guide to data quality tools, from Great Expectations and Soda to Monte Carlo, Elementary, dbt tests, and Bruin. Which are open source, which catch freshness and completeness problems, which enforce data contracts, and which run inside the pipeline rather than beside it.
Kateryna Kozachenko
12 min read
Stripe Analytics Pipeline: Why Stripe's Reporting Runs Out and How to Build Your Own
Stripe's dashboard, Sigma, and Data Pipeline each stop somewhere. Here is where they stop, how a three-layer Stripe analytics pipeline fixes it, how the tooling options compare, and why starting from a free local template beats assembling a stack.
Arsalan Noorafkan
12 min read

The Best Change Data Capture (CDC) Tools for Databases in 2026
An honest 2026 comparison of CDC tools for databases: Debezium, Bruin's ingestr, Estuary Flow, Fivetran, Airbyte, and AWS DMS. Log-based vs query-based CDC, when you actually need streaming, and how to pick without over-engineering.
Kateryna Kozachenko
11 min read

Migrate from Fivetran to Bruin: cut Postgres-to-BigQuery costs
A practical Fivetran migration guide for moving PostgreSQL to BigQuery with Bruin and ingestr. Validate parity, reduce MAR-based spend, and run a governed open-source data ingestion pipeline.
Arsalan Noorafkan
11 min read
The Best Data Transformation Tools in 2026
An honest 2026 guide to data transformation tools, from dbt and SQLMesh to Dataform, Coalesce, Matillion, and Bruin. Which handle SQL and Python in one project, which give column-level lineage, which run on Snowflake, BigQuery, and Databricks, and which need a platform team.
Kateryna Kozachenko
13 min read
Launch: Data Apps
Dashboards are nice and all, but sometimes you want to go crazy with your data visualization, no?

Burak Karakan
3 min read

Bruin Data Apps vs Lightdash, Retool, Streamlit, and Hex
A 2026 comparison of Bruin Data Apps against Lightdash, Retool, Microsoft Power Apps, Streamlit, and Hex, plus AI app builders like v0 and Claude Artifacts. Which let you turn a question into a purpose-built, operational interface on live, governed warehouse data, and which stop at dashboards, code, or a pretty frontend with no trustworthy backend.
Kateryna Kozachenko
13 min read
Shopify to ClickHouse: build a fast ecommerce analytics warehouse
Learn how to load Shopify data into ClickHouse, choose an ingestion method, model a bronze-silver-gold ecommerce warehouse, and use Bruin to spend less time maintaining data tooling.
Arsalan Noorafkan
14 min read
How to choose an incremental data loading strategy
Choose between full refresh, append, merge, delete+insert, time_interval, and SCD2 based on source updates, deletes, keys, late data, and history requirements.
Arsalan Noorafkan
12 min read
What Is a Data App? Definition, Examples, and BI Differences
What is a data app? Learn how data applications combine trusted data, business logic, and workflows, and how they differ from BI, dashboards, and reports.
Arsalan Noorafkan
17 min read

The Best Way to Replicate a Database into Snowflake (2026)
How to replicate Postgres, MySQL, SQL Server, or another database into Snowflake in 2026. Managed vs open-source options, a step-by-step with Bruin's ingestr CLI, incremental loading, and the Snowflake-specific gotchas (staging, warehouses, cost).
Kateryna Kozachenko
9 min read

Is It Safe to Give AI Access to Your Data?
The honest answer is: it depends entirely on the controls around the AI, not the AI itself. Here's a practical framework for evaluating PII handling, permissions, data residency, and self-hosting before you connect an AI data analyst to your warehouse.
Kateryna Kozachenko
13 min read
NULL Keys Silently Break BigQuery Joins and MERGEs
A NULL in a join key never matches itself, so your incremental MERGE quietly duplicates rows and your joins quietly drop them. Here is why it happens, why the obvious null-safe fix (IS NOT DISTINCT FROM) turns your join into a cross join, and the OR-form that stays a hash join, with a full BigQuery benchmark.

Sabri Karagonen
9 min read

What Is the Fastest Open-Source Data Ingestion Tool?
A practical 2026 look at the fastest open-source data ingestion tools: Bruin's ingestr, dlt, Sling, Embulk, Airbyte, and Meltano. What 'fast' actually means (throughput, cold start, and time-to-first-sync), and how to benchmark it on your own data.
Kateryna Kozachenko
9 min read
Migrating from Metabase to Bruin DAC
How to decide whether a Metabase dashboard belongs in self-hosted Bruin DAC or Bruin Cloud, what to migrate first, and why the move is more about metric ownership than chart widgets.
Arsalan Noorafkan
8 min read
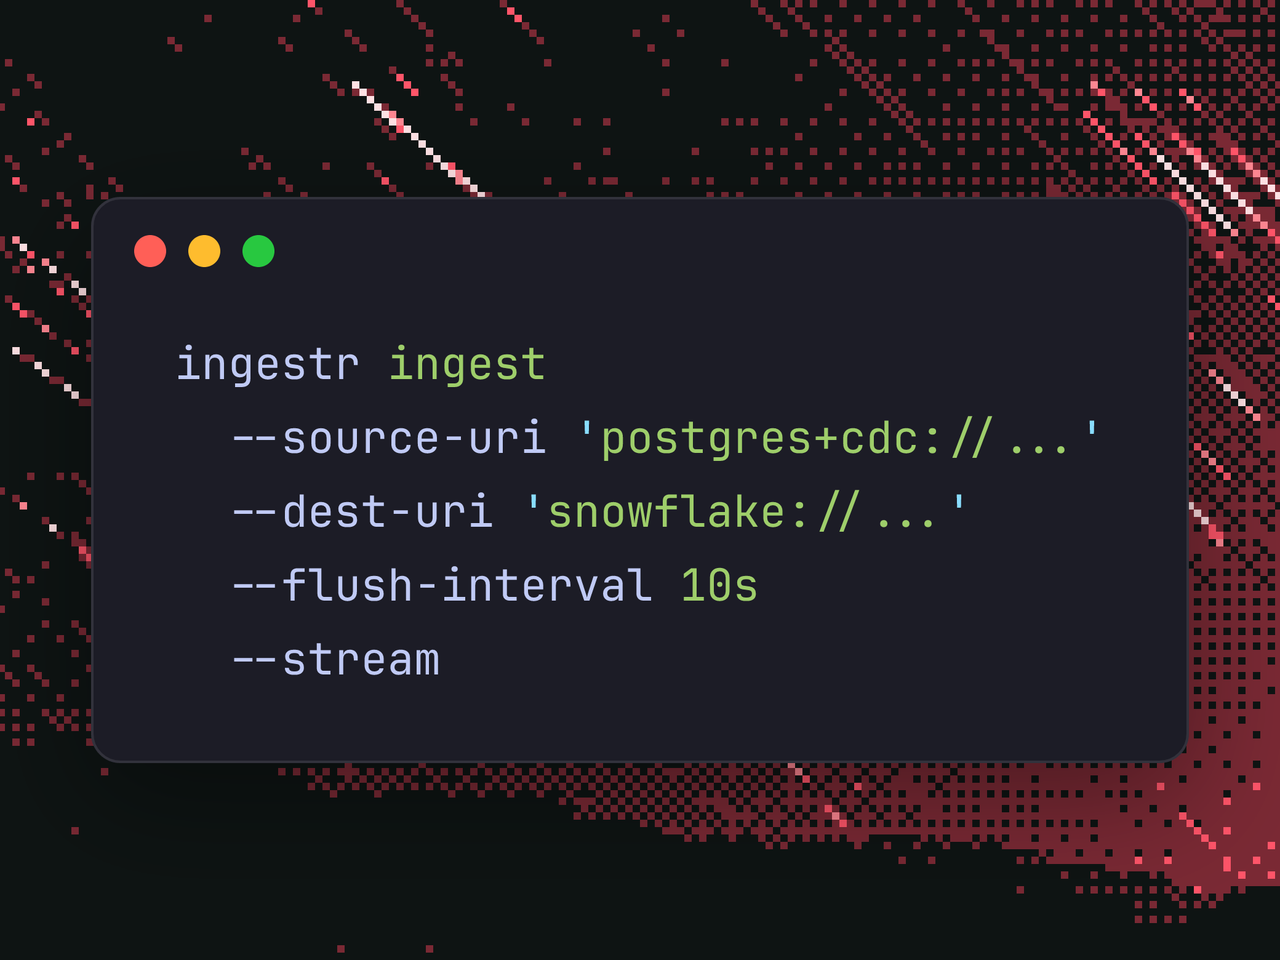
Launching: ingestr CDC
Bringing sanity back into Change Data Capture (CDC) workloads
Burak Karakan
8 min read

How Do I Know the AI's Answer Is Correct?
An AI data analyst that hands you a number and no way to check it is asking for faith, not giving you an answer. Here's what verifiable AI answers actually require: the SQL it ran, the lineage back to raw rows, and definitions that don't drift between questions.
Kateryna Kozachenko
12 min read

What Is a SQL Unit Test? Examples, Benefits, and How to Write One
A SQL unit test checks a query's logic with controlled input rows and an expected result. Learn what SQL unit tests cover, how they differ from data quality checks, and how to write them with Bruin.
Arsalan Noorafkan
10 min read
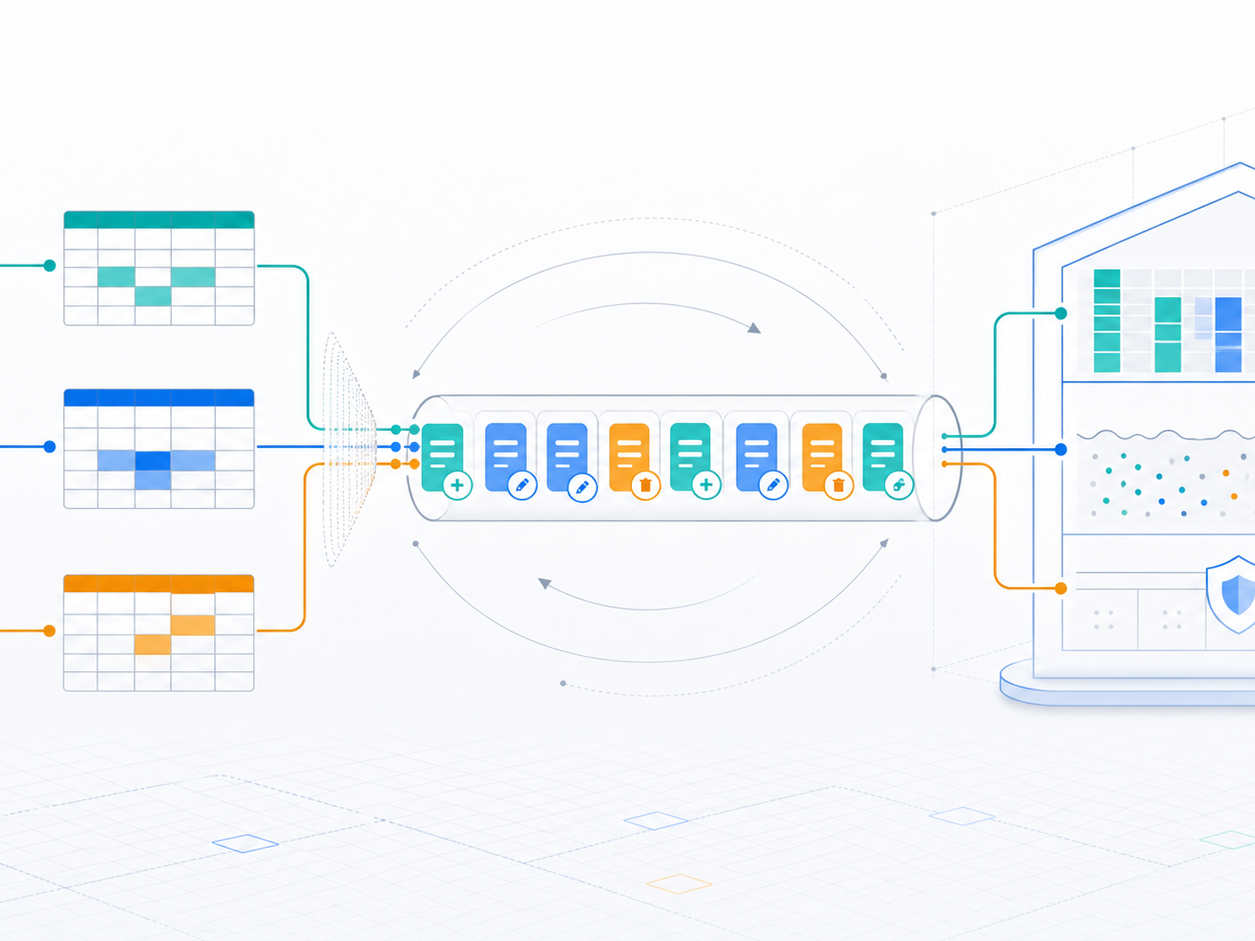
What is CDC in data engineering? Change data capture explained
What is CDC in data engineering? Learn how change data capture records database changes, differs from ETL and incremental loading, and when to use it.
Arsalan Noorafkan
15 min read
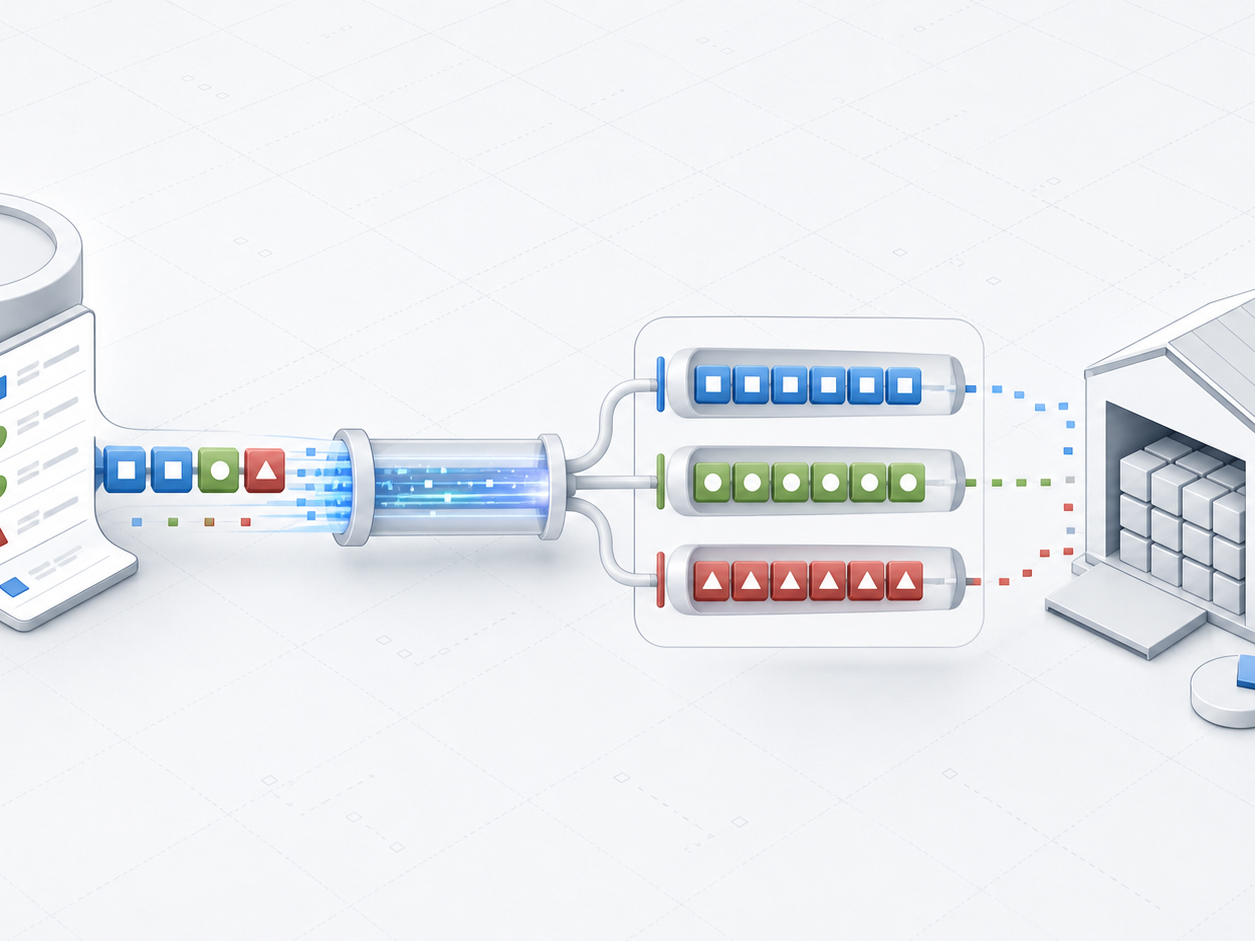
What is CDC streaming? Change data capture guide
What is CDC streaming? Learn how it reads database logs, where Kafka fits, how it differs from batch CDC, and when its operational cost is worth it.
Arsalan Noorafkan
14 min read

The Best Tool to Load API Data into a Data Warehouse (2026)
How to load data from REST APIs into Snowflake, BigQuery, or Databricks in 2026. The hard parts (pagination, auth, rate limits, JSON flattening), and the best tools: Bruin's ingestr for known SaaS APIs, dlt for arbitrary REST, plus managed options.
Kateryna Kozachenko
9 min read
What Is Reverse ETL? Definition, Examples, and When to Use It
Reverse ETL explained in plain terms: how warehouse data moves back into CRMs, marketing tools, support systems, internal apps, and workflows, how it differs from ETL and ELT, and when teams should use it.
Arsalan Noorafkan
10 min read
Migrating from Pentaho Data Integration to Bruin
A practical migration plan for moving Pentaho PDI and Kettle jobs to Bruin. The Bruin team can help with onboarding and migration planning for ingestr, SQL/Python assets, quality checks, DAC dashboards, MCP, and AI analytics.
Arsalan Noorafkan
10 min read
Pentaho vs Bruin: A Modern Alternative for Data Pipelines
A practical comparison of Pentaho and Bruin for teams evaluating PDI, Kettle, and legacy ETL alternatives. Bruin offers onboarding and migration planning for governed pipelines, DAC dashboards, MCP, and AI analytics.
Arsalan Noorafkan
9 min read

The Best Open-Source ELT Tools in 2026
A 2026 guide to open-source ELT tools across extract-load and transform: Airbyte, dlt, ingestr, Sling, Meltano, dbt, SQLMesh, and Bruin. Which cover the whole ELT flow, which do one step, and how to assemble a stack you can actually maintain.
Kateryna Kozachenko
11 min read
Agentic Salesforce to Snowflake ELT: From One Prompt to a Governed Pipeline
How Bruin CLI, Bruin MCP, Bruin Cloud, and agent skills can build and maintain a Salesforce to Snowflake ELT pipeline across bronze, silver, and gold layers.
Arsalan Noorafkan
10 min read
Bruin Project Competition: over 70 end-to-end data pipelines from the Data Engineering Zoomcamp community
A recap of the first Bruin Project Competition: how it started with DataTalksClub Data Engineering Zoomcamp, what participants built, which Bruin features they used, and what future builders can learn.
Arsalan Noorafkan
8 min read

How to Build a Salesforce to Snowflake Pipeline with Bruin
A simple guide to ingesting Salesforce data into Snowflake, modelling bronze, silver, and gold layers, and using Bruin agents for dashboards, Slack reports, activation, and self-healing pipelines.
Arsalan Noorafkan
8 min read
Learning AI Programming, Agentic Data Engineering, and AI Data Analysis
A practical guide to the best open and official courses for AI programming, agentic data engineering, and AI data analysis - organized by career path, experience level, and project goal.
Arsalan Noorafkan
18 min read

The Best Way to Replicate a Database into BigQuery (2026)
How to replicate Postgres, MySQL, or SQL Server into BigQuery in 2026. Managed vs open-source options including Datastream, a step-by-step with Bruin's ingestr CLI, incremental loading, partitioning, and BigQuery cost gotchas.
Kateryna Kozachenko
9 min read
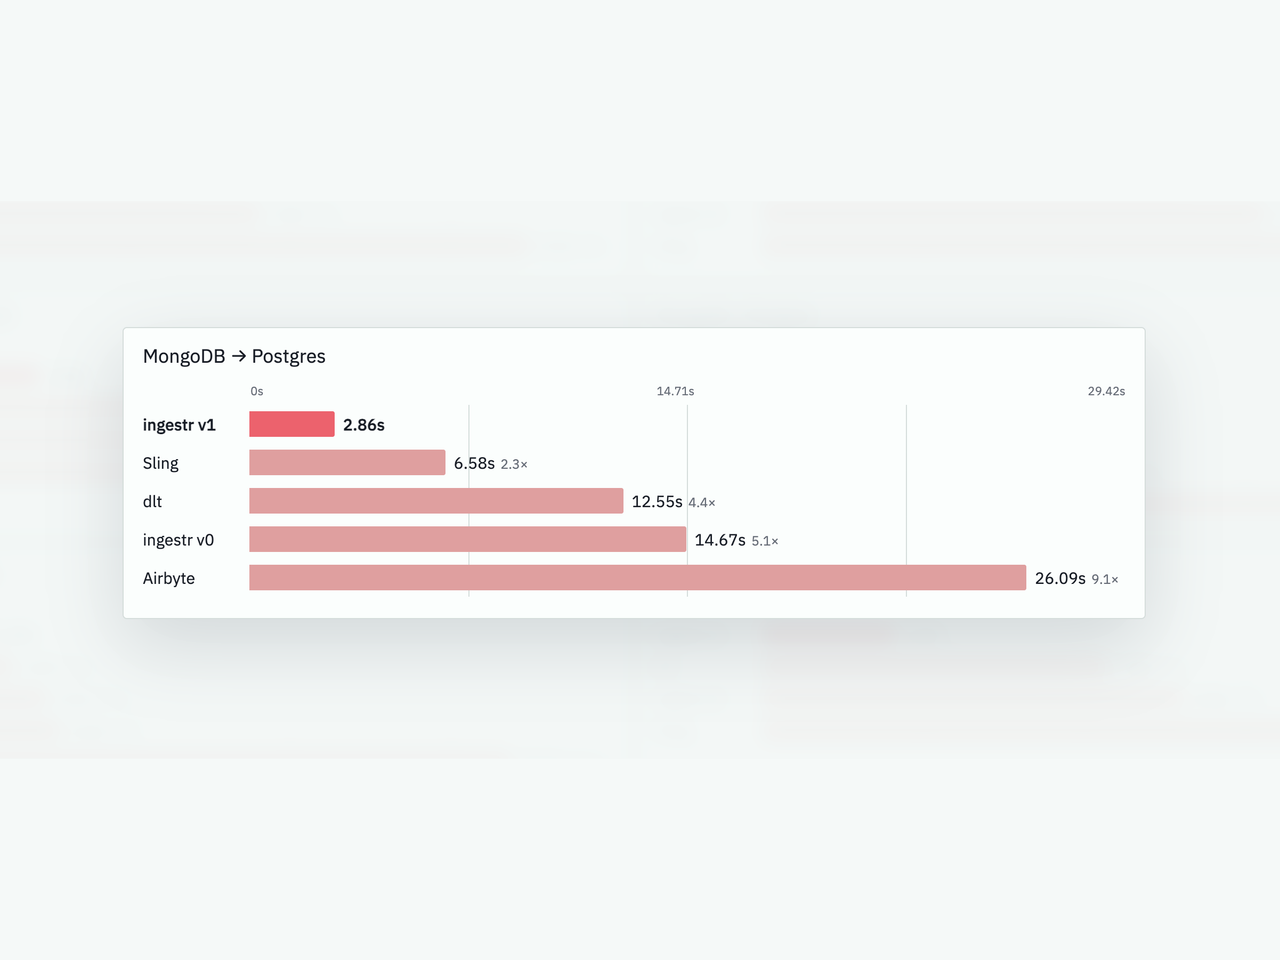
dlt Alternatives: Bruin, Airbyte, Sling, Meltano, and Fivetran Compared
A practical comparison of dlt alternatives for data ingestion: Bruin CLI, ingestr, Airbyte, Sling, Meltano, and Fivetran, including a MongoDB to Postgres benchmark.
Arsalan Noorafkan
10 min read

BigQuery TVFs for AI Agents: A Lightweight Semantic Layer Pattern
BigQuery table-valued functions can give AI data agents a small, governed query interface without asking them to write full SQL against raw warehouse tables.
Arsalan Noorafkan
4 min read

How Do I Know My Ecommerce Numbers Are Right?
The number one question ecommerce operators ask about their data isn't 'what's my revenue', it's 'can I trust this figure'. Here's why your numbers disagree across tools, and how to make a single figure you can defend in a board meeting.
Kateryna Kozachenko
12 min read
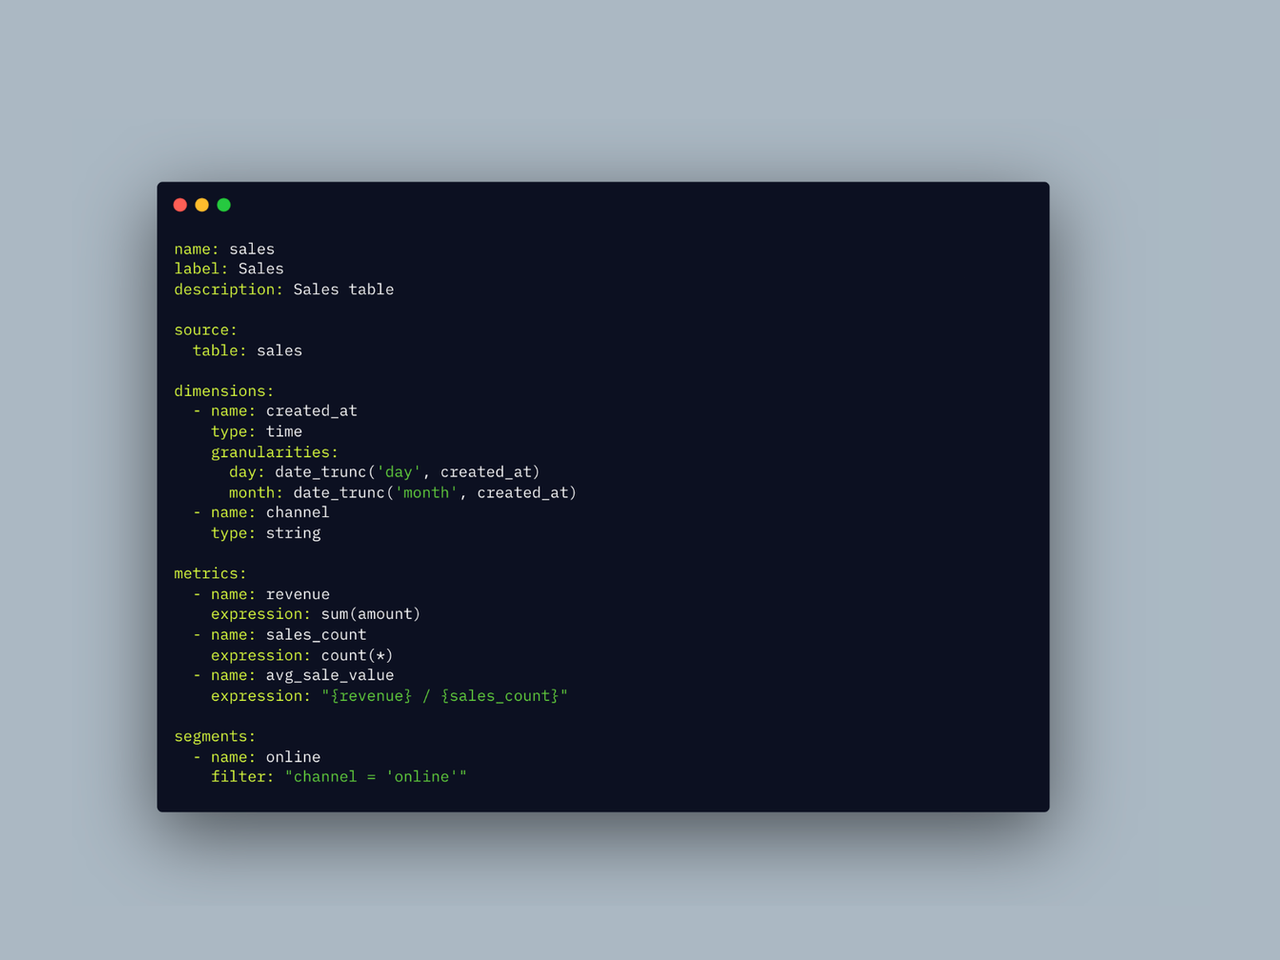
Best Semantic Layer Tools in 2026: dbt, Cube, Looker, Power BI, Lightdash, Bruin
Compare semantic layer tools for BI, dbt metrics, reusable definitions, dashboards, and AI agents: dbt, Cube, Looker, Power BI, Tableau, AtScale, Lightdash, and Bruin.
Arsalan Noorafkan
10 min read
What Is a Semantic Layer?
A practical explanation of semantic layers, why metric definitions drift across dashboards, and how tools like Bruin CLI and DAC turn reusable metrics, dimensions, filters, and segments into SQL.
Arsalan Noorafkan
8 min read

How to Sync Salesforce Data into a Warehouse (2026)
A practical 2026 guide to syncing Salesforce into Snowflake, BigQuery, or Databricks. The Salesforce API basics, managed vs open-source options, a step-by-step with Bruin's ingestr CLI, incremental syncs on SystemModstamp, and the gotchas.
Kateryna Kozachenko
9 min read

Fable 5 vs Bruin for Data Analysis: Can a Frontier Model Be Your Data Analyst?
Fable 5 is one of the most capable AI models yet, and people are asking whether it can replace a data analyst. Here is an honest look at what Fable 5 does well for data analysis, where it stops, and how it compares to a purpose-built AI data analyst like Bruin.
Kateryna Kozachenko
7 min read
The 9 Best AI Dashboard Tools and Builders in 2026
Compare the best AI dashboard tools and builders for 2026. See which tools turn natural-language prompts into live dashboards, connect to company data, expose APIs, and fit business teams.
Kateryna Kozachenko
15 min read

The Best Data Ingestion Tools in 2026
An honest 2026 guide to data ingestion tools, from Fivetran and Airbyte to dlt, Sling, Meltano, and Bruin's ingestr. Which are open source, which connect to live company data, which support CDC and incremental loads, and which fit a modern AI data stack.
Kateryna Kozachenko
12 min read

The Best Python Library for Data Ingestion in 2026
A 2026 comparison of Python data ingestion options: dlt, PyAirbyte, the Singer SDK, pandas plus SQLAlchemy, and ingestr, Bruin's pip-installable CLI. Which to import, which to shell out to, and when a library is the wrong tool entirely.
Kateryna Kozachenko
9 min read

Migrating from Python to Go: ingestr v1
We have rebuilt ingestr, Bruin's open-source ingestion CLI, from the ground up to be faster, more reliable, and easier to use. Here is how we did it and what it means for your data pipelines.
Burak Karakan
6 min read
The Best AI BI Tools in 2026
An honest 2026 guide to AI business intelligence tools, from ThoughtSpot, Power BI Copilot, Tableau Pulse, and Looker to Snowflake Cortex, Databricks Genie, and Bruin. Which let business teams ask questions in plain English, which connect to live company data, and which can actually replace a BI stack.
Kateryna Kozachenko
12 min read

The Best Way to Replicate a Database into Databricks (2026)
How to replicate Postgres, MySQL, or SQL Server into Databricks in 2026. Managed vs open-source options, a step-by-step with Bruin's ingestr CLI, loading into Delta tables and Unity Catalog, incremental loading, and Databricks-specific gotchas.
Kateryna Kozachenko
9 min read
Segment vs Hightouch vs Census Reverse ETL: 2026 Comparison
Segment vs Hightouch vs Census for reverse ETL: compare warehouse-native activation, CDP profiles, Fivetran-owned syncs, governance, and where Bruin fits.
Arsalan Noorafkan
18 min read

How to Build a Data Ingestion Pipeline Without Managing Servers (2026)
A 2026 guide to serverless data ingestion: run a pipeline without standing up or babysitting a server. Managed SaaS vs a serverless CLI on Cloud Run, Lambda, or GitHub Actions, with a concrete example using Bruin's ingestr and the tradeoffs.
Kateryna Kozachenko
9 min read

AI Data Analyst vs ChatGPT, Claude, and Coding Agents: What's the Difference?
Can you just use ChatGPT, Claude, or a coding agent like Codex to analyze your company data? Here is the honest difference between a general AI model and a purpose-built AI data analyst, why a model alone is not enough, and what it takes to get trustworthy answers from live company data.
Kateryna Kozachenko
10 min read
The Best Power BI Copilot Alternatives in 2026
Looking for a Power BI Copilot alternative? An honest 2026 comparison of ThoughtSpot, Tableau Pulse, Looker, Snowflake Cortex, Sigma, and Bruin, for teams that want plain-English answers on live data without per-seat licensing or DAX.
Kateryna Kozachenko
10 min read

The Cheapest Way to Move Large Data Volumes into a Warehouse (2026)
A 2026 guide to moving large data volumes into Snowflake, BigQuery, or Databricks cheaply. Where the cost actually goes (per-row fees, egress, compute), the levers that cut it, and why open-source bulk-loading tools like Bruin's ingestr win at scale.
Kateryna Kozachenko
9 min read

Best Data Pipeline Tools 2026: Airflow, Bruin, Dagster, Prefect, and Mage
A practical 2026 shortlist of the best data pipeline tools: Bruin, Apache Airflow, Dagster, Prefect, and Mage. Which one is the best all-in-one pipeline tool, the lightest Airflow alternative for a small data team, and the best open-source data engineering platform, plus a direct Dagster vs Prefect answer.
Arsalan Noorafkan
10 min read
Score XGBoost models in BigQuery, no Python required
Most batch ML scoring pipelines waste DS time pulling data into Python containers to do arithmetic the warehouse already does. Here is the trick, the receipt, and a copy-paste Jinja macro that translates an XGBoost model to SQL, validated on DuckDB.
Sabri Karagonen
8 min read
How to Get Full Attribution Coverage Between Adjust and Firebase
A one-time SDK setup for game studios: cross-write Adjust ADID, Firebase user_pseudo_id, and your own user_id so installs join cleanly across both systems. AppsFlyer, Singular, and Branch follow the same pattern.
Sabri Karagonen
6 min read

Answer, Build, Act: What the Next AI Data Analyst Actually Does
AI data analysts started by answering questions. The useful ones now also build (dashboards, reports, pipelines) and act (pause bad ad spend, fix broken reports, alert the right owner). Here is why answering alone is not enough, and what it takes to act safely on live company data.
Kateryna Kozachenko
8 min read
Deterministic A/B Test Bucketing
Make A/B test bucketing a pure function of (salt, user_id) so iOS, Android, web, and BigQuery all derive the same variant for the same user, and so you can preview cohort balance in the warehouse before launch.
Sabri Karagonen
7 min read
Exporting Adjust Raw Data to Google Cloud Storage
A short setup guide for getting Adjust raw exports landing in a GCS bucket, plus the parameters you should be sending to Adjust to get attribution right.
Sabri Karagonen
5 min read

Reconciling Shopify, Amazon, and Ad Platforms Into One Answer
Your revenue lives in Shopify, your marketplace sales in Amazon, and your spend across Meta, Google, and TikTok. Getting one honest number for 'what did we make and what did it cost' means reconciling all of it. Here's how to stop doing it in a spreadsheet.
Kateryna Kozachenko
12 min read
How to Run Reliable Firebase A/B Tests
Firebase counts users as 'in variant B' when the variant never actually reached their device. Here's the proxy-parameter setup that gives you a cohort you can defend.
Sabri Karagonen
7 min read

The Best Text-to-SQL Tools in 2026
An honest 2026 guide to text-to-SQL tools that turn natural language into queries, from Vanna AI, WrenAI, and Defog to Snowflake Cortex, Databricks Genie, and Bruin. Which are open source, which connect to live company data, and which go beyond generating SQL to deliver trustworthy answers.
Kateryna Kozachenko
11 min read
Why It's Reasonable to Be Skeptical About AI in Data - and Why It's Fixable
A practical framework for building an AI context layer using open-source tools, turning skepticism about AI in data engineering into a working solution with self-healing pipelines and iterative team adoption.
Arsalan Noorafkan
25 min read

Best Mobile Game Analytics Tools in 2026
Compare mobile game analytics tools for 2026: Firebase/GA4, GameAnalytics, Amplitude, Adjust, AppsFlyer, BigQuery, Snowflake, Looker, Hex, and Bruin.
Kateryna Kozachenko
12 min read
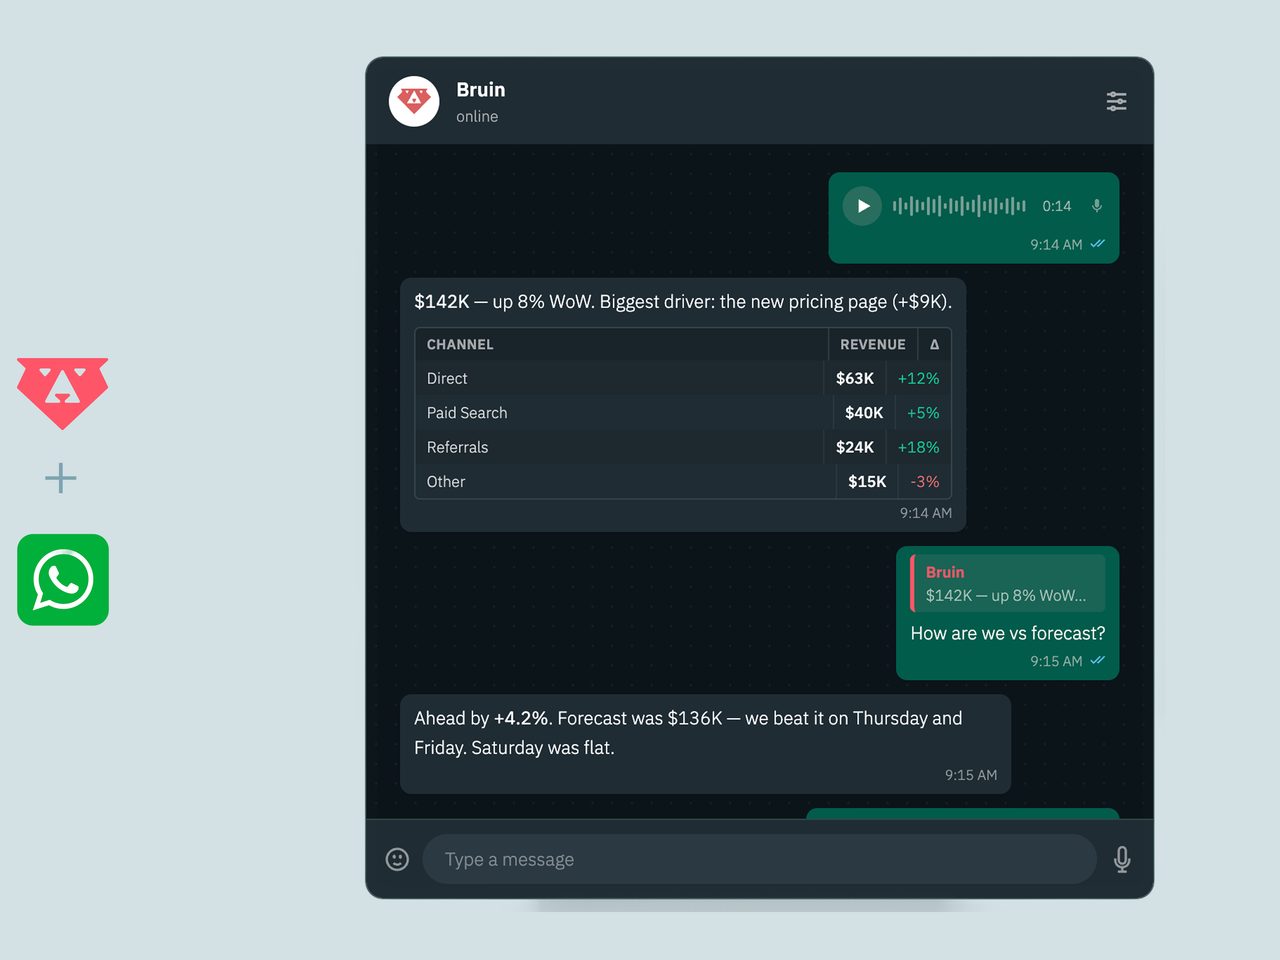
AI Data Analyst on WhatsApp
Most AI data analysts live in Slack or a browser. Bruin runs in WhatsApp too. Here is why field, sales, and ops teams prefer asking their data questions there, what it takes to make it actually work, and how to roll it out safely.
Kateryna Kozachenko
14 min read
The Best AI Data Analyst Tools for Slack in 2026
An honest 2026 guide to AI data analyst tools that live natively in Slack. Bruin, Dot, Querio, ThoughtSpot, Question Base, Clearfeed, and eesel AI compared, with pros, cons, and which one fits which kind of team.
Kateryna Kozachenko
14 min read
From Prompt to Dashboard: How Conversational AI Is Replacing the BI Request Queue
For 20 years, self-serve BI has meant 'learn to build your own dashboard.' In 2026, prompting replaces point-and-click, and the BI request queue dies with it. A practical look at where conversational BI works, where it does not, and how to run a data team around it.
Kateryna Kozachenko
18 min read

Multi-Location, Multi-Channel Inventory: One View of What You Actually Have
When stock is spread across warehouses, 3PLs, Amazon FBA, and retail, nobody can answer 'how much do we actually have and where'. Here's how to build one unified inventory view with velocity, days of cover, and reorder alerts, without a data team.
Kateryna Kozachenko
12 min read
AI Data Analyst vs Traditional BI: How to Choose in 2026
Honest 2026 framework for picking between an AI data analyst and traditional BI tools. When each one wins, the hybrid pattern most teams land on, and how to migrate without breaking trust in your data.
Kateryna Kozachenko
12 min read
Building an AI Data Analyst Sucks
I'll teach you how to do this, and you'll get mad at me for it.
Burak Karakan
6 min read
Meet Bruin’s AI data analyst in Slack, Teams, and browser
Bruin’s AI data analyst is an AI-native BI interface for asking questions about company data and getting back answers that are fast, relevant, and usable in context.

Kateryna Kozachenko
11 min read
Go is the Best Language for AI Agents
Pull up your agents folks, I'll convince you why Go is the best language for them.
Burak Karakan
8 min read

Returns Analysis and Return-Fraud Detection Without a Data Team
Returns quietly eat ecommerce margin, and a slice of them are fraud. Here's how to analyze returns by SKU, reason, and cost, and how to spot wardrobing, serial returners, and refund-not-returned abuse, without hiring a data team.
Kateryna Kozachenko
13 min read
The 8 Best AI Data Analyst Tools in 2026
An honest 2026 guide to the AI data analyst tools worth shortlisting. Bruin, ThoughtSpot, Hex, Dot, Seek AI, Defog, Power BI Copilot, and ChatGPT with MCP - with pros, cons, pricing, and when each one actually fits across SaaS, ecommerce, gaming, and agencies.
Kateryna Kozachenko
18 min read
Bruin VS Code Extension: The Architectural Challenge of Integrating Vue.js Webviews
How we built a rich, interactive VS Code extension using Vue.js webviews, bridging Node.js extension code with a modern frontend through message passing.

Djamila Baroudi
6 min read
Introducing Bruin MCP: Your AI Agent's Data Toolkit
Bruin now supports the Model Context Protocol, letting AI agents in Cursor, Claude Code, and other editors query databases, ingest data, compare tables, and build pipelines-all through natural language.
Burak Karakan
6 min read
My 3 Month Internship Journey
My first internship experience at Bruin, where I shipped real features and learned a lot.

Mustafa Ersan
5 min read
Python vs SQL: Choosing the Right Tool
A practical guide to choosing between Python and SQL for data transformations. Learn when to use each tool, common antipatterns to avoid, and decision frameworks that work.
Burak Karakan
12 min read
dbt vs Bruin: Why End-to-End Wins Over Transformation-Only
dbt only handles transformations, leaving you with a complex stack. Bruin provides end-to-end pipelines with data ingestion, SQL & Python transformations, quality checks, and built-in orchestration-all in one open-source tool.
Burak Karakan
15 min read
The Effective LLM Multi-Tenant Security Solution
A practical pattern to secure LLM-generated SQL in multi-tenant systems by pre-filtering data with CTEs so the model never sees cross-tenant rows.
Sabri Karagonen
12 min read
Fivetran vs Bruin: Beyond Data Ingestion
Fivetran only handles data ingestion, leaving you with a complex stack. Bruin provides end-to-end pipelines with ingestion, transformations, quality checks, and Python custom connectors-all in one open-source tool.
Burak Karakan
12 min read
How I Survived (and Thrived) in the Zombie Apocalypse
A story about hunting zombie tasks in a distributed environment

Alberto Gomez
10 min read
The Hidden Costs of DIY Data Pipelines
Building your own data pipelines seems cost-effective until you do the math. Here's a detailed breakdown of what companies actually spend on homegrown solutions.
Burak Karakan
10 min read
Launch: Bruin CLI
Bruin CLI is an open-source data pipeline tool built with Go, with built-in data ingestion, transformation, and data quality checks.
Burak Karakan
8 min read

No-code data platform is a lie
A critical look at the limitations of no-code data platforms and why code-first approaches provide more flexibility and long-term value for growing data teams.
Burak Karakan
9 min read

Summarising User Behaviour: The Users Daily Table
Creating a comprehensive daily user behavior table in BigQuery using Firebase analytics data to track user engagement metrics and analyze patterns over time.
Sabri Karagonen
14 min read
Unnesting Firebase Events Table
A step-by-step guide to unnesting and transforming Firebase events data in BigQuery for easier analysis and more efficient queries.
Sabri Karagonen
12 min read

The Pains of Data Ingestion
Why is data ingestion so hard? This post explores the challenges of data ingestion and introduces ingestr, Bruin's open-source solution to simplify the process.
Burak Karakan
8 min read
Firebase Events Table
A comprehensive guide to querying and working with the Firebase events table in BigQuery, including useful functions and techniques for easier data analysis.
Sabri Karagonen
15 min read
The Mythical Data Team
How companies are approaching data teams wrong, and why a cultural shift towards treating data as a core value is needed for organizations to become truly data-driven.
Burak Karakan
6 min read

Firebase Analytics BigQuery Export: Official Docs and Settings
Use the official Firebase BigQuery export flow, then fix the settings most teams miss: region, streaming export, advertising identifiers, and the 60-day table expiry.
Sabri Karagonen
5 min read